Structure is free, labels are expensive
Clustering receives only the table \(X\), no labels, and returns groups of similar rows.
segment
customers
compress
a palette of \(k\) colors is a clustering of the pixels
organize
documents: the road to topic modeling
The path of this part
- Define and judgedistance, internal and external indices
- k-meansLloyd's algorithm by hand, local minima
- Choosing kelbow, silhouette, two more indices
- Distrust the indexnoise scores 0.40; scaling changes the ruler
- Interpretwhat each group is, in the original units
What clustering is, and how it is judged
| classification | clustering | |
|---|---|---|
| input | \(X\) and \(y\) | only \(X\) |
| "correct" means | predicting \(y\) on new rows | satisfying a criterion you chose |
| validated with | a held-out test set | no test set is possible without labels |
what "similar" means
a distance adds up columns: grams drown millimeters. Scaling is part of the clustering.
how it is judged
internal indices use only \(X\); external ones (the Adjusted Rand Index, ARI) compare with known labels, here only to check the internal ones.
The Adjusted Rand Index, by hand
Truth: \(\{1,2,3\}, \{4,5,6\}\). A clustering: \(\{1,2\}, \{3,4\}, \{5,6\}\).
- Of the 15 pairs, they agree on 10: (1,2) and (5,6) together in both; 8 cross pairs apart in both.
- Rand index \(= 10/15 = 0.667\). But random labels also agree on many pairs.
- The ARI subtracts chance: 0.242.
Answers: 1.0 (the ARI ignores names) and 0.0.
k-means: points near a center
\[ J = \sum_{j=1}^{k} \sum_{x_i \in C_j} \lVert x_i - \mu_j \rVert^2, \qquad \mu_j = \text{mean of } C_j \]The inertia: each point's squared distance to the center \(\mu_j\) of its group \(C_j\). Circular: centers depend on groups, groups on centers. Lloyd's algorithm alternates:
- assign: each point goes to its nearest center;
- update: each center moves to the mean of its points.
Lloyd by hand: a bad start
Two unit squares, around \((1.5, 1.5)\) and \((6.5, 5.5)\); both centers start in the left one, \(c_1 = (1,1)\) and \(c_2 = (2,2)\). Predict. \(x_4 = (2,2)\) sits on \(c_2\): which group will it join, and will the algorithm notice?
Simulator: Lloyd, one step at a time
The spokes join each point to its center; the inertia is the sum of their squared lengths. Its history never goes up.
Simulator: try to beat the mean
Try. Drag the centers and watch which group contributes most to the inertia. Then move every center to its mean.
Initialization and local minima
300 points in three well-separated blobs; k-means with one start, 100 seeds.
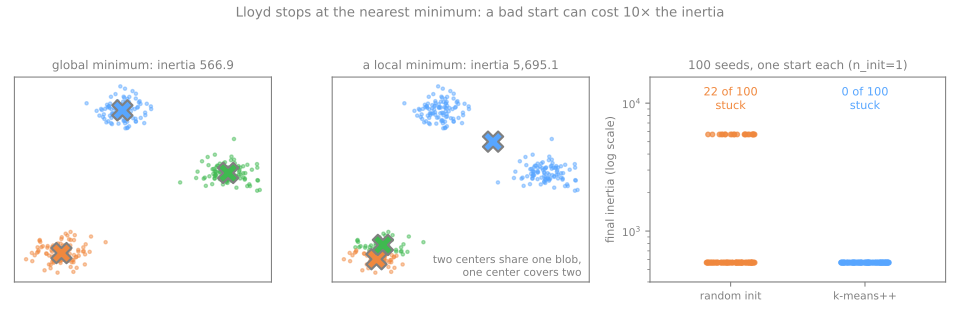
Random starts: stuck in 22 of 100 runs (inertia up to 5,703.3, ten times the best, 566.9). k-means++: 0. Random with n_init=10 (restart, keep the lowest inertia): 0. Two centers share one blob, and moving any single center or point makes it worse.
Choosing \(k\): the inertia cannot
- Adding a center can only lower the inertia; with \(k = n\) it is 0.
- The elbow: the \(k\) after which a new group buys much less. A heuristic, often ambiguous, read on a curve that always goes down.
The silhouette, by hand
\(s(i) = \dfrac{b(i) - a(i)}{\max(a(i), b(i))}\), with \(a\) = mean distance to its own group and \(b\) = to the nearest other group. Predict. \(x_1\) is the corner farthest from the other square: will \(s(x_1)\) be near 1, near 0 or negative?
Simulator: the silhouette of every point
Click a point to see its two circles: \(a\) in its own color, \(b\) in the neighbor's. The bars are every point's silhouette, sorted by group.
Two more internal indices
Calinski–Harabasz, CH (higher is better)
\[ \mathrm{CH} = \frac{B/(k-1)}{W/(n-k)} \]\(W\) = the inertia; \(B\) = the spread of the centers around the overall mean, each weighted by its group size. Eight points: \(B = 82\), \(W = 4\): \(\mathrm{CH} = (82/1)/(4/6) = 123\)
Davies–Bouldin, DB (lower is better)
for each group, its worst neighbor: \((s_i + s_j)/d(\mu_i, \mu_j)\), with \(s_i\) the mean distance of group \(i\)'s points to its center
Eight points: \((0.7071 + 0.7071)/6.4031 = 0.2209\)
On real data: 342 penguins
Four standardized measurements; the species (Adelie 151, Gentoo 123, Chinstrap 68) kept aside, only for the ARI.
| \(k\) | inertia | silhouette | CH | DB | ARI (check) |
|---|---|---|---|---|---|
| 2 | 565.7 | 0.532 | 482.2 | 0.714 | 0.655 |
| 3 | 379.4 | 0.447 | 441.7 | 0.944 | 0.793 |
| 4 | 300.4 | 0.400 | 400.4 | 0.944 | 0.637 |
| 5 | 232.6 | 0.378 | 411.2 | 0.973 | 0.572 |
Two different questions
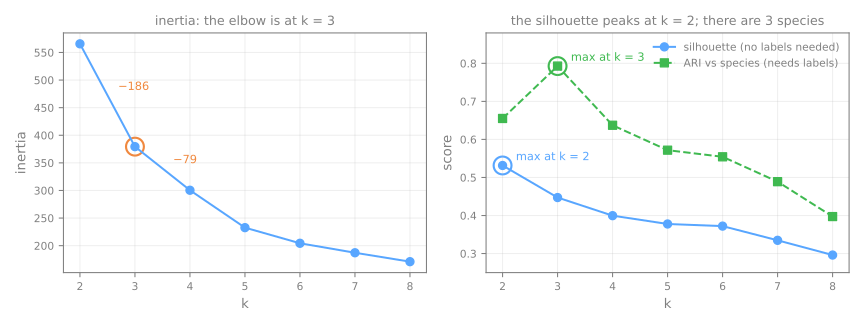
- The elbow says 3 (the inertia drops 186 from 2 to 3, then only 79); silhouette, CH and DB all say 2; the species are 3.
- Adelie and Chinstrap differ mainly in bill length: merging them really is more compact.
Simulator: sweep \(k\) on eight datasets
Try. Clean blobs, unequal sizes, circles, noise: when do the elbow and the silhouette agree?
The silhouette of pure noise
300 uniform points: no structure at all.
| \(k\) | 2 | 3 | 4 | 5 |
|---|---|---|---|---|
| silhouette | 0.359 | 0.379 | 0.4 | 0.382 |
A ruler: rerun the same pipeline with each column shuffled independently and report both silhouettes. The lab does it, at step 4.
Scaling matters, and the silhouette will not tell you
Standard deviations: body mass 801.95 g, bill depth 1.97 mm, about 400 times smaller.
| silhouette | ARI with species | |
|---|---|---|
| raw units | 0.580 | 0.331 |
| standardized | 0.447 | 0.793 |
Raw: three weight bands, well separated. An internal index compares partitions of the same space; when the scaling changes, the ruler changes. Scale by an argument about units.
Interpreting clusters
Back to the original columns, with a groupby:
| cluster | bill length | bill depth | flipper | mass (g) | n |
|---|---|---|---|---|---|
| 0 | 47.5 | 15.0 | 217.2 | 5076.0 | 123 |
| 1 | 38.2 | 18.1 | 188.4 | 3584.7 | 132 |
| 2 | 47.5 | 18.8 | 196.9 | 3902.0 | 87 |
Heavy birds with long flippers and shallow bills; small birds with short bills; long and deep bills. (Cluster 0 is exactly the Gentoo; the only confusion is Adelie against Chinstrap.)
Summary
- No labels, no answer key: the algorithm always returns a partition.
- k-means minimizes the inertia by alternating assign and update; it stops at a local minimum, so restart it (
n_init). - The inertia cannot choose \(k\); silhouette, CH and DB measure separation, not whether the partition is the one you want.
- An index is not a certificate: noise scores 0.40, and a change of scale changes the ruler.
- A group must be described, in the original columns: a choice, not a discovery.
Four questions before believing a clustering
- Did I scale? If not, it probably sorts by the column with the largest unit.
- Did I restart enough? An inertia ten times too high is possible.
- Where did \(k\) come from? The silhouette preferred 2 penguin groups where there are 3 species.
- Did I compare with shuffled data? Pure noise reaches a silhouette of 0.40.
Grouping 178 wines without labels, steps 1 to 6
- 178 Italian wines, 13 chemical measurements; the cultivar column is sealed until step 9: every decision is taken without labels.
- Download the lab notebook and open it in Jupyter or Colab. At every step, answer the Predict before running.
- Simulations: the raw distance is proline (step 2) and one shuffle is one draw (step 4).
1. load, and seal the cultivar
2. scale, and why the indices cannot decide it
3. choose \(k\): elbow and silhouette
4. the ruler: shuffled data
5. fit \(k = 3\), inspect each cluster
6. profile in the original units
Pace: steps 1 and 2 and the first simulation in 12 min; steps 3 and 4 and the second in 13 min; steps 5 and 6 in 10 min.