The Frontier
The last stop of the arc that began with least squares in 1805. Its centerpiece is a map of the field: every technique of the previous lessons, grouped by the job it does, next to the techniques that lie just beyond this course, each with the lesson where it was taught and where to read more. Around the map: how transfer learning and foundation models changed the economics of machine learning, where the classical toolbox you built still wins, and the problems the field has not solved yet.
The lesson has no dataset of its own. Its two labs are guided exercises on this page: you click the map, route requests to the right tool, and check with a few lines of Python three claims the text makes — that the retrieval half of a RAG system is a k-NN, that the reward model of RLHF is a logistic regression, and that LoRA trains a tiny fraction of a model. Every number quoted comes from the code blocks on this page or from the papers cited.
How this lesson is organized
The lesson has two approaches. Each has slides, text and a lab to do in class; the quiz at the end covers the fundamental one. Start with the fundamental approach: the advanced one builds on it.
| Fundamental approach | Advanced approach | |
|---|---|---|
| question | Where does each technique of the course sit, and when do you reach for a foundation model instead of the classical toolbox? | How do the frontier's tools work inside, how do you test them, and what is still unsolved? |
| content | the map of the field and four walks through it; transfer learning by feature extraction and by fine-tuning; foundation models, scaling and the ways to adapt an LLM (zero-shot, few-shot, fine-tuning, RAG); the classical toolbox inside the LLM stack; where classical ML still wins; routing | LoRA in detail, counted layer by layer, and why a low-rank update can be enough; the memory of fine-tuning; why trees still lead on tables; TabPFN and how to test a challenger; open problems |
| in-class lab | route the problem, steps 1 to 4 | count, compress and test, steps 5 to 7 |
| by the end, you can | place a technique on the map and name what it builds on; tell feature extraction, fine-tuning, prompting and RAG apart; recognize a k-NN, a logistic regression and a leakage problem inside an LLM system; route a request to a foundation model, to the classical stack or to both | count what LoRA trains and what it saves in memory; say when a low-rank update is enough and when it is not; explain how TabPFN predicts without training; design a fair test of a challenger against the classical default |
This lesson has no notebook. The code of each step runs in any Python with scikit-learn: open a new Colab notebook (nothing to install) and copy the blocks from this page, in order. Steps 1 and 4 need no code.
Fundamental approach
One question drives this part: where does everything you learned sit, and when is a foundation model the right tool? The answer starts from the map, goes through the two ideas that changed the economics of the field (reuse a pre-trained model; adapt it with a prompt instead of a training run), finds the pieces of this course inside the new stack, and ends with a routing rule: which kind of problem goes to which kind of model.
This part follows one path in four stages, drawn below: 1. map the field; 2. reuse, don’t restart; 3. find the classical inside; 4. route the problem. Each stage links to its section, and in the slides a strip at the bottom shows which stage you are in.
- Map the fieldevery technique by the job it does; four walks
- Reuse, don’t restarttransfer learning, foundation models, prompting
- Find the classical insidesoftmax, k-NN, logistic regression, leakage
- Route the problemwhere classical wins; what to use when
Fundamental approach slides
Click the slides and use the ← → arrows to navigate; F opens full screen and Esc shows every slide. Open the slides in a new tab
1. A map of the field
Stage 1. Techniques are grouped by the question they answer: prepare the data, find structure without labels, turn text into numbers, predict with lines, neighbors, trees or networks, measure honestly, explain, automate, operate. Two more groups hold what this course did not reach: other problem shapes (sequences, recommendations, rewards, graphs) and the frontier itself. Solid chips were taught here, and the code is the lesson; dashed chips lie beyond. Click a technique to see what it is, what it builds on, what builds on it, and where to read more.
Reading the map
The links between chips are the point of the map. Four walks through it:
- Retrieval-augmented generation builds on k-NN and dense embeddings. A 1951 idea (vote among the nearest points) and a 2013 idea (words as vectors) are the retrieval half of a 2020 system. Step 2 of the lab builds that half.
- Alignment (RLHF) trains a reward model on pairs of answers: the probability that answer A is preferred to answer B is modeled as \(\sigma(r_A - r_B)\), the sigmoid of a score difference. That is a logistic regression, fitted with the same cross-entropy you minimized in the logistic regression lesson. Step 3 of the lab fits one.
- Evaluating LLM systems builds on classification metrics and cross-validation & leakage. A benchmark whose questions leaked into the training data is the same bug as a scaler fitted before the split, at internet scale.
- Tabular foundation models are the one place where the frontier attacks the stronghold of gradient boosting head on. They are discussed in the advanced approach.
The same map as a list
Every node of the map, grouped the same way. This list is the map's source: it works without JavaScript and in print. marks the lesson where a technique was taught, marks what lies beyond this course, marks where to read (a classic paper first, then a modern resource).
Foundations — what learning from data means
- A history of learning machines — From least squares (1805) to the perceptron, two AI winters, deep learning and LLMs: each wave recombines older ideas with more data and compute.
F1. Introduction & History · Turing (1950) · Sutton, "The Bitter Lesson" (2019) - Learning paradigms — Supervised (learn from labels), unsupervised (find structure), reinforcement (learn from rewards): the paradigm follows from the feedback the data carries.
F2. The ML Landscape · Hastie, Tibshirani & Friedman (2009) · James et al. (2023) - Generalization & no free lunch — What matters is the error on data the model has not seen, and no algorithm wins on every problem: the assumptions must match the data. Builds on learning paradigms.
F2. The ML Landscape · Wolpert (1996) · Domingos (2012)
Data — from raw records to a model-ready matrix
- Exploratory data analysis — Look before modeling: distributions, missing values, outliers, associations. Split first, then explore only the training part.
D1. Exploratory Data Analysis · Anscombe (1973) · Matejka & Fitzmaurice (2017) - Preprocessing — Scale numeric features, encode categories, transform skewed columns and impute missing values, always fitted on the training data only. Builds on EDA.
D2. Data Preprocessing · Little & Rubin (2019) · scikit-learn: preprocessing - Pipelines — Chain the preprocessing and the model into one estimator, so that every fit happens inside the right split. Builds on preprocessing.
D3. Pipelines · Buitinck et al. (2013) · scikit-learn: pipelines - Data-centric AI & label quality — Better data often beats a better model: find label errors, remove duplicates, document how the dataset was collected. Builds on EDA.
beyond this course · Northcutt, Athalye & Mueller (2021) · Gebru et al. (2021)
Unsupervised learning — structure without labels
- PCA — Rotate the data onto the directions of largest variance and keep the first few, to compress, denoise or plot. Builds on preprocessing.
U1. Dimensionality Reduction · Pearson (1901) · Jolliffe & Cadima (2016) - t-SNE & UMAP — Non-linear maps that keep each point's neighbors close, for looking at high-dimensional data; the distances between clusters mean little. Builds on PCA, k-NN.
U1. Dimensionality Reduction · van der Maaten & Hinton (2008) · McInnes, Healy & Melville (2018) - k-means — Split the rows into k compact groups around centroids; choose k with inertia and silhouette. Builds on preprocessing.
U2. Clustering · Lloyd (1982) · Arthur & Vassilvitskii (2007) - Hierarchical clustering — Merge the closest groups one step at a time and read the result as a dendrogram; cut it at the level you need. Builds on k-means.
E1. Hierarchical Clustering · Ward (1963) · Sokal & Rohlf (1962) - DBSCAN & HDBSCAN — Clusters as dense regions of any shape; the points in sparse regions are labeled as noise. Builds on k-NN.
U2. Clustering · Ester et al. (1996) · Campello, Moulavi & Sander (2013) - Anomaly detection — Flag the rare points that do not fit the rest: isolation forests, density scores, reconstruction errors. Builds on DBSCAN, random forest.
beyond this course · Liu, Ting & Zhou (2008) · scikit-learn: outlier detection - Self-supervised & contrastive learning — Invent a prediction task from the data itself (hide a word, match two crops of the same image) and learn representations without any human label. Builds on dense embeddings, neural networks.
beyond this course · Devlin et al. (2019) · Chen et al. (2020)
Text — turning words into vectors
- Bag-of-words & TF-IDF — Count the tokens of each document and down-weight the ones every document uses: sparse, fast, interpretable.
E2. Text Representation · Salton & Buckley (1988) · Manning, Raghavan & Schütze (2008) - Dense embeddings — Words and sentences as short dense vectors whose geometry encodes meaning: texts with similar meaning land close together. Builds on bag-of-words.
E2. Text Representation · Mikolov et al. (2013) · Reimers & Gurevych (2019) - Topic models: LDA & BERTopic — Find the themes of a corpus: LDA as mixtures of words; BERTopic as clusters of embeddings, described by a class-based TF-IDF. Builds on dense embeddings, UMAP, HDBSCAN, TF-IDF.
E3. Topic Modeling & BERTopic · Blei, Ng & Jordan (2003) · Grootendorst (2022) - Subword tokenization — How LLMs cut text: byte-pair encoding builds a vocabulary of frequent fragments, so no word is ever out of the vocabulary. Builds on bag-of-words.
beyond this course · Sennrich, Haddow & Birch (2016) · Hugging Face courses
Linear models — lines, planes and margins
- Linear regression — Least squares: the closed-form fit, residuals, R² and the assumptions behind the inferences.
R1. Linear Regression · Galton (1886) · James et al. (2023) - Gradient descent — Walk downhill on the loss, one batch or mini-batch at a time: the optimizer behind almost every modern model. Builds on linear regression.
R2. Gradient Descent & Regularization · Ruder (2016) · Bottou, Curtis & Nocedal (2018) - Ridge & Lasso — Penalize large weights (L2) or push some of them to exactly zero (L1): a little bias bought for much less variance. Builds on linear regression.
R2. Gradient Descent & Regularization · Hoerl & Kennard (1970) · Tibshirani (1996) - Logistic & softmax regression — Probabilities through the sigmoid or the softmax, trained on cross-entropy; the output layer of every classifier network. Builds on linear regression, gradient descent.
C1. Logistic Regression · Berkson (1944) · Cox (1958) - Support vector machines & kernels — The boundary with the widest margin, bent into curves by a kernel that never builds the new features. Builds on logistic regression, Ridge.
C5. Support Vector Machines · Cortes & Vapnik (1995) · Hsu, Chang & Lin (2003) - Probabilistic & Bayesian models — Distributions over parameters and predictions (naive Bayes, Bayesian regression, Gaussian processes): uncertainty by construction. Builds on linear regression, Ridge.
beyond this course · Rasmussen & Williams (2006) · Murphy (2022)
Instance-based learning — let the neighbors vote
- k-nearest neighbors — Keep the training set and predict from the k closest rows; the scaling and the choice of k do all the work. Builds on preprocessing.
C2. k-Nearest Neighbors · Fix & Hodges (1951) · Cover & Hart (1967) - Approximate nearest-neighbor search — Graph and quantization indexes (HNSW, FAISS) find the almost-nearest vectors among billions in milliseconds: the engine of vector databases. Builds on k-NN, dense embeddings.
beyond this course · Malkov & Yashunin (2020) · Johnson, Douze & Jégou (2019)
Trees & ensembles — the tabular workhorses
- Decision trees — Recursive yes/no questions, each chosen to reduce impurity; easy to read, unstable on their own.
M1. Decision Trees · Breiman et al. (1984) · Quinlan (1986) - Random forest — Average hundreds of de-correlated trees, each grown on a bootstrap sample; the out-of-bag error comes for free. Builds on decision trees.
M2. Random Forest · Breiman (2001) · Louppe (2014) - Gradient boosting: XGBoost, LightGBM, CatBoost — Add small trees one at a time, each one fitted to the gradient of the loss: the usual winner on tabular data. Builds on decision trees, gradient descent.
M3. Gradient Boosting · Friedman (2001) · Chen & Guestrin (2016) · Ke et al. (2017) - Stacking — Train a meta-model on the out-of-fold predictions of several different models. Builds on cross-validation, gradient boosting.
beyond this course · Wolpert (1992) · scikit-learn: ensembles
Neural networks — from the perceptron to deep learning
- Perceptron, MLP & backpropagation — Stacked logistic units with non-linear activations, trained by the chain rule: the hidden layers learn their own features. Builds on logistic regression, gradient descent.
E4. Neural Networks · Rosenblatt (1958) · Rumelhart, Hinton & Williams (1986) - Convolutional networks — Small filters shared across the whole image, stacked from edges to textures to objects. Builds on MLP.
beyond this course · LeCun et al. (1998) · Krizhevsky, Sutskever & Hinton (2017) · Insper ANN-DL - Recurrent networks & LSTMs — A state carried along a sequence, step by step; gates let an LSTM remember across long spans. Builds on MLP.
beyond this course · Hochreiter & Schmidhuber (1997) · Insper ANN-DL - Transformers & attention — Every token looks at every other one and takes a weighted average, with weights from learned similarities (a softmax). Builds on MLP, dense embeddings, softmax.
beyond this course · Vaswani et al. (2017) · Alammar (2018) · Insper ANN-DL - Generative models: VAEs, GANs, diffusion — Learn the distribution of the data itself and sample new images, sounds or molecules from it. Builds on MLP, convolutional networks.
beyond this course · Goodfellow et al. (2014) · Ho, Jain & Abbeel (2020) · Insper ANN-DL
Evaluation & model selection — honest numbers
- Classification metrics — Confusion matrix, precision, recall, F1, MCC: pick the metric from the cost of each kind of error.
C3. Classification Metrics · van Rijsbergen (1979) · Chicco & Jurman (2020) - ROC, PR & imbalanced data — Curves over every threshold; class weights, threshold moving and resampling when the positives are rare. Builds on classification metrics.
C4. ROC, PR & Imbalanced Data · Fawcett (2006) · Saito & Rehmsmeier (2015) - Cross-validation & data leakage — Rotate the validation fold for a steadier estimate, keep every fitted step and every future fact away from the rows you score on, and compare models on the same folds (nested CV grades the choice itself). Builds on pipelines, generalization.
C6. Cross-Validation & Data Leakage · Stone (1974) · Kapoor & Narayanan (2023) - Model selection & bias–variance — The bias–variance decomposition, validation and learning curves, regression to the mean: tell underfitting from overfitting and choose the complexity from validation scores, not from hope. Builds on cross-validation, Ridge & Lasso.
M4. Model Selection · Geman, Bienenstock & Doursat (1992) · Belkin et al. (2019) - Calibration & conformal prediction — Probabilities that mean what they say, and prediction sets that contain the true answer with a guaranteed rate. Builds on classification metrics, cross-validation.
beyond this course · Guo et al. (2017) · Angelopoulos & Bates (2021)
Explainability & responsibility — why the model says what it says
- Interpretable by design — Linear models and shallow trees, whose reasoning can be read directly; for high-stakes decisions they are often enough. Builds on logistic regression, decision trees.
E5. Explainability · Rudin (2019) · Molnar, Interpretable Machine Learning - Permutation importance — Shuffle one feature on held-out data and measure how much the score drops. Builds on random forest, cross-validation.
E5. Explainability · Fisher, Rudin & Dominici (2019) · scikit-learn: permutation importance - SHAP & LIME — Explain one prediction: each feature's contribution, from Shapley values (SHAP) or from a local linear surrogate (LIME). Builds on gradient boosting, permutation importance.
E5. Explainability · Ribeiro, Singh & Guestrin (2016) · Lundberg & Lee (2017) - Ethics & responsibility — Models learn the bias in historical decisions; privacy, consent and accountability are part of the job, not an afterthought.
F2. The ML Landscape · Obermeyer et al. (2019) · Bender et al. (2021) - Algorithmic fairness — Formal criteria (demographic parity, equalized odds), why they cannot all hold at once, and how to audit a model group by group. Builds on ethics, classification metrics.
beyond this course · Hardt, Price & Srebro (2016) · Barocas, Hardt & Narayanan (2023) - Mechanistic interpretability — Open the network itself and find the features and circuits its neurons compute. Builds on transformers, SHAP.
beyond this course · Olah et al. (2020) · Templeton et al. (2024)
AutoML — searching for the model
- Random search & Bayesian optimization — Sample hyperparameters at random, or let a surrogate model decide where to try next (Optuna). Builds on model selection.
E6. AutoML · Bergstra & Bengio (2012) · Snoek, Larochelle & Adams (2012) - Successive halving & Hyperband — Give every candidate a small budget, keep the best fraction, give the survivors more. Builds on random search.
E6. AutoML · Jamieson & Talwalkar (2016) · Li et al. (2018) - Full-pipeline AutoML — Search over the preprocessing, the model family and its hyperparameters together, often ending in an ensemble. Builds on pipelines, Bayesian optimization, stacking.
E6. AutoML · Feurer et al. (2015) · Erickson et al. (2020) - Neural architecture search — Search the network's architecture itself: layers, widths, connections. Builds on Bayesian optimization, MLP.
beyond this course · Zoph & Le (2017) · Elsken, Metzen & Hutter (2019)
MLOps — models in production
- Serving, versioning & reproducibility — Persist the fitted pipeline, pin the data and library versions, serve predictions behind an API. Builds on pipelines.
E7. MLOps · Sculley et al. (2015) · Breck et al. (2017) - Monitoring & drift — Watch the inputs, the predictions and the outcomes in production, and retrain when the world moves. Builds on classification metrics, serving.
E7. MLOps · Gama et al. (2014) · Rabanser, Günnemann & Lipton (2019) - Model cards & documentation — A short standard sheet: what the model is for, how it was evaluated, on whom it fails. Builds on ethics, serving.
E7. MLOps · Mitchell et al. (2019) · Hugging Face: model cards
Other problem shapes — beyond one row, one label
- Time-series forecasting — Predict the next values of a sequence from its lags and seasonality, with validation that only ever looks backward. Builds on cross-validation, gradient boosting.
beyond this course · Hyndman & Athanasopoulos (2021) · Makridakis, Spiliotis & Assimakopoulos (2022) - Recommender systems — Predict who wants what from sparse interactions: matrix factorization, then embeddings of users and items searched by nearest neighbors. Builds on PCA, dense embeddings, approximate nearest neighbors.
beyond this course · Koren, Bell & Volinsky (2009) · Covington, Adams & Sargin (2016) - Reinforcement learning — An agent learns by acting and collecting rewards: bandits, Q-learning, policy gradients. The paradigm was introduced in the ML landscape lesson. Builds on learning paradigms, MLP.
beyond this course · Sutton & Barto (2018) · Mnih et al. (2015) - Graph neural networks — Learn on networks of connected entities (molecules, social networks, road maps) by passing messages between neighbors. Builds on MLP, k-NN.
beyond this course · Kipf & Welling (2017) · Sanchez-Lengeling et al. (2021)
The frontier — foundation models and open questions
- Transfer learning & fine-tuning — Start from a pre-trained model: use its embeddings as features, or keep training its weights (all of them, or a low-rank LoRA slice) on your labels. Discussed below. Builds on dense embeddings, MLP.
beyond this course · Howard & Ruder (2018) · Hu et al. (2022) - Foundation models & LLMs — One very large model pre-trained on self-supervised tasks, then adapted to many downstream tasks; scale in data, parameters and compute keeps buying new abilities. Discussed below. Builds on transformers, self-supervised learning, transfer learning.
beyond this course · Kaplan et al. (2020) · Brown et al. (2020) · Bommasani et al. (2021) - Prompting & in-context learning — Describe the task and show a few examples in the prompt; no weight changes. Builds on foundation models.
beyond this course · Brown et al. (2020) · Wei et al. (2022) - Retrieval-augmented generation (RAG) — Embed the question, fetch the nearest passages from a document store, put them in the prompt: k-NN over embeddings feeding an LLM. Builds on k-NN, approximate nearest neighbors, dense embeddings, foundation models.
beyond this course · Lewis et al. (2020) · Karpukhin et al. (2020) - Alignment: RLHF and successors — Tune a model toward human preferences, through a reward model fitted on compared answer pairs (RLHF) or directly on those pairs (DPO). Builds on reinforcement learning, logistic regression, foundation models.
beyond this course · Christiano et al. (2017) · Ouyang et al. (2022) · Rafailov et al. (2023) - Evaluating LLM systems — Benchmarks saturate and leak into training data; held-out tasks, LLM-as-a-judge and human preference arenas are the new validation sets. Builds on classification metrics, cross-validation & leakage.
beyond this course · Liang et al. (2022) · Zheng et al. (2023) · Sainz et al. (2023) - Multimodal models — One embedding space for images and text (CLIP), then models that read, see and listen at once. Builds on self-supervised learning, transformers, convolutional networks.
beyond this course · Radford et al. (2021) · Dosovitskiy et al. (2021) - Agents & tool use — LLMs that plan, call tools (search, code, APIs) and act in a loop; how to evaluate them and keep them safe is largely open. Builds on prompting, RAG, reinforcement learning.
beyond this course · Yao et al. (2023) · Schick et al. (2023) - Tabular foundation models — A transformer pre-trained on millions of synthetic tables predicts a new small table in one forward pass (TabPFN), challenging boosted trees on small data. Discussed below. Builds on gradient boosting, transformers, model selection.
beyond this course · Grinsztajn, Oyallon & Varoquaux (2022) · Hollmann et al. (2023) · Hollmann et al. (2025) - Causal machine learning — From "what predicts Y?" to "what happens to Y if we act?": treatment effects, uplift, double machine learning. Builds on linear regression, cross-validation, gradient boosting.
beyond this course · Chernozhukov et al. (2018) · Hernán & Robins, Causal Inference: What If - Efficient models: distillation & quantization — Smaller, cheaper models that keep most of the quality: a student trained on a teacher's soft labels, weights stored in 4 or 8 bits. Builds on foundation models, transfer learning.
beyond this course · Hinton, Vinyals & Dean (2015) · Dettmers et al. (2023) - AI regulation & governance — Risk-based law and risk-management frameworks: the EU AI Act, NIST's AI RMF, and in Brazil the LGPD (article 20: the right to ask for review of automated decisions) and the AI bill PL 2338/2023. Builds on ethics, fairness, model cards, interpretable models.
beyond this course · EU AI Act (2024) · NIST AI RMF 1.0 (2023) · PL 2338/2023 (Senado)
2. Transfer learning: stop starting from zero
Stage 2. Classical supervised learning trains each model from scratch on its own labeled data. Transfer learning reuses knowledge: pre-train a large model on a huge generic corpus, then adapt it to your task. There are two ways to adapt:
- feature extraction: freeze the pre-trained model and use its representations as features for a classical head. You did this: sentence embeddings fed to a logistic regression or to a clustering step;
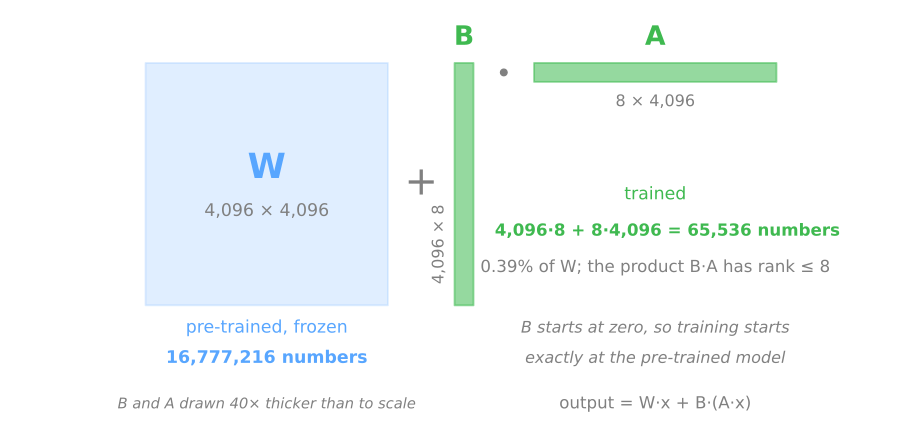
- fine-tuning: continue training some or all of the weights on your labeled data, typically 10²–10⁴ examples instead of 10⁶. LoRA (Hu et al., 2022) trains only a low-rank correction \(W + BA\) of each weight matrix, with \(B\) and \(A\) thin; for a \(4096 \times 4096\) matrix and rank 8, that is \(2 \times 4096 \times 8 = 65{,}536\) trainable numbers instead of \(16{,}777{,}216\), 0.39% of them.
The figure draws that count: the frozen matrix and the two thin matrices that LoRA trains (figure script). The advanced approach repeats the count for a whole 7-billion-parameter model.
This inverted the data economics of the field. ULMFiT (Howard & Ruder, 2018) and BERT (Devlin et al., 2019) showed that a language model pre-trained on unlabeled text, then fine-tuned, beats models trained from scratch on text classification with a fraction of the labels. Tasks that once demanded massive labeled datasets became feasible with hundreds of examples.
3. Foundation models
Scale the recipe: transformer architectures, self-supervised pre-training (predict masked or next tokens: the labels are free, so any text becomes training data), billions of parameters. Something qualitatively new appears. A foundation model (Bommasani et al., 2021) is one very large pre-trained model adapted to many downstream tasks: the GPT family, Claude, Gemini and Llama for text; CLIP and its successors for vision and language; Whisper for speech.
Why scale? Kaplan et al. (2020) measured that the test loss of language models falls as a smooth power law in the number of parameters, the size of the data and the compute, over several orders of magnitude. That regularity made it rational to spend on ever larger training runs. Sutton's "Bitter Lesson" (2019) reads the same history: over 70 years, general methods that exploit more computation have beaten hand-built knowledge.
With large language models, adaptation gets lighter still:
| Adaptation | Labeled data needed | What happens |
|---|---|---|
| zero-shot | none | describe the task in the prompt |
| few-shot / in-context | a handful | show examples in the prompt; no weights change |
| fine-tuning (full / LoRA) | hundreds+ | update the weights, or a low-rank slice of them |
| RAG | none (needs documents) | retrieve relevant passages by nearest-neighbor search over embeddings and put them in the context |
"Classify this support ticket as billing, technical or other": in 2018, a labeling project and a trained classifier; today, often a single prompt (Brown et al., 2020, showed GPT-3 doing new tasks from a few examples in the prompt). Prompting became the new fit() for a broad class of language tasks. What did not change: you still need a labeled test set to know whether the prompt works.
4. The classical toolbox in an LLM world
Stage 3. Look inside the modern stack and this course is everywhere:
- the output layer of an LLM is a softmax regression over the vocabulary; training is mini-batch gradient descent with weight decay (an L2 penalty, as in Ridge) on cross-entropy;
- RAG systems are k-NN over embeddings; a vector database is an approximate nearest-neighbor engine;
- the reward model of RLHF is a logistic regression on pairs of answers;
- evaluating an LLM system is precision/recall thinking plus honest held-out design; test questions that leak into training data are the field's current leakage problem;
- BERTopic already composed foundation-model embeddings with UMAP, HDBSCAN and TF-IDF.
Where classical ML still wins
Stage 4. Reach for the classical stack, not a foundation model, when:
| Situation | Why classical wins |
|---|---|
| Tabular data (churn, credit, pricing, demand) | gradient boosting still leads the benchmarks on medium-sized tables (Grinsztajn et al., 2022); LLMs are poor at tables of numbers |
| Latency / cost / scale (decisions in milliseconds, billions of rows) | a logistic regression scores a row in microseconds, for almost nothing |
| Regulated decisions | odds ratios and SHAP values can be shown to an auditor; a prompt cannot |
| Small, well-structured problems | a 2,000-row dataset needs bias–variance control, not a trillion parameters |
| Determinism and stability | fixed model + fixed input = fixed output; LLMs sample |
The first row has a challenger: TabPFN (Hollmann et al., 2023, 2025), a transformer pre-trained on millions of synthetic tables, which predicts a new small table in a single forward pass, with no training and no tuning. On classification tables of up to 10,000 rows it is worth testing against boosted trees, the way you tested every model in this course; the advanced approach shows how it works and how to test it.
Routing: what to use when
The frontier practitioner's skill is routing: perception and language go to foundation models, structured prediction goes to the classical stack, and real systems use both. An LLM reads the free-text complaint, a gradient-boosted model scores the churn risk, and MLOps monitors both. In practice:
- free text, images or sound, few labels: a foundation model. Start with a prompt (zero- or few-shot); with a few hundred labels, embeddings plus a classical head (feature extraction); fine-tune (LoRA) when neither is good enough;
- the answer must come from your own documents: RAG, a k-NN over the embeddings of those documents feeding the prompt;
- a table of numbers and categories: the classical stack. Gradient boosting as the default; a logistic regression when the decision must be audited or scored in microseconds;
- both kinds of input: both models. The foundation model turns the text into features or labels; the classical model takes them as columns and decides;
- whatever the route: a labeled test set the system never saw, and the same honest validation as in the cross-validation lesson.
5. Summary: the frontier in five lines
- Every technique has a place on the map, and most of the frontier builds on chips this course taught: k-NN, embeddings, logistic regression, gradient descent, cross-validation.
- Transfer learning reuses a pre-trained model: frozen, as a feature extractor for a classical head, or fine-tuned on your labels (LoRA trains a thin slice of each matrix).
- Foundation models are pre-trained on self-supervised tasks at scale; an LLM can be adapted with a prompt, a few examples in the prompt, retrieved passages (RAG) or fine-tuning.
- Inside the LLM stack sits this course: a softmax output layer, mini-batch gradient descent, k-NN retrieval, a logistic reward model, and leakage as the evaluation problem.
- Route the problem: language and perception to foundation models, tables to the classical stack, real systems to both, and always a labeled test set.
| request | first tool | why |
|---|---|---|
| free text, few labels | a prompt, then embeddings + a classical head | pre-trained knowledge replaces labels |
| answers from your own documents | RAG | k-NN over embeddings feeds the prompt |
| a table, cost or audit matter | gradient boosting or logistic regression | accurate, cheap, explainable |
| a small table (≤ 10,000 rows) | boosting, with TabPFN as a challenger | test both on the same folds |
Fundamental lab — route the problem
The problem. A company has hired you to decide, for each new request that reaches the data team, which part of the toolbox gets it. Before routing anything, you check with your own code two claims of this lesson that the routing depends on: that the retrieval half of RAG is a k-NN, and that the reward model of RLHF is a logistic regression. The checks use tiny artificial data, built so that each one shows a single mechanism; they are not benchmarks.
How to do this lab in class (about 30 min, in pairs)
- This lesson has no notebook. Open a new Colab notebook (or any Python with scikit-learn) and copy the code of each step from this page, in order, in a single session. Steps 1 and 4 need no code.
- This lab is steps 1 to 4. The advanced lab continues from step 5.
- Every step starts with a Predict: answer it with your partner before running the cell or opening the solution. Getting the prediction wrong is what makes the result memorable.
- After running, compare with the output and the reading on this page. Every output here is exactly what the code prints.
- The Simulations ask you to write a small Python experiment: change one input and watch what happens to the output. No hand calculations. The solution is collapsed right below: try before opening it.
- Suggested pace: step 1 in 5 min; step 2 and its simulation in 10 min; step 3 and its simulation in 10 min; step 4 in 5 min.
Step 1 — find your course on the map
Predict. Of all the chips on the map, which one do the most other chips build on: a model, a representation or a way of validating? Make a guess before clicking.
Use the map: the green ring shows what builds on the chip you click, and the panel lists it under leads to. Click k-nearest neighbors, then Logistic & softmax regression, then Perceptron, MLP & backpropagation, Dense embeddings and Cross-validation & data leakage, and count the green rings of each.
Solution
The map has 69 techniques in 14 groups: 38 taught in this course, 31 beyond it. The chip most built upon is Perceptron, MLP & backpropagation (9 chips build on it: convolutional and recurrent networks, transformers, self-supervised learning, generative models, graph networks, reinforcement learning, neural architecture search, transfer learning), followed by Dense embeddings and Cross-validation & data leakage, 7 each. k-NN and logistic regression have 5 each: k-NN leads to t-SNE and UMAP, DBSCAN, approximate nearest-neighbor search, graph networks and RAG; logistic regression to SVMs, the MLP, transformers, interpretable models and alignment (RLHF). The two most reused ideas after the network are a representation and a way of validating, not a model: what you learned about measuring honestly is as central to the frontier as any algorithm.
Step 2 — the retrieval half of RAG is a k-NN
Predict. The question below shares the words choose and k-NN with one of the six passages and no word with most of the others. Which passage comes back first? How similar do you expect the second one to be?
import numpy as np
from sklearn.feature_extraction.text import TfidfVectorizer
from sklearn.neighbors import NearestNeighbors

passages = [
    "k-NN predicts from the k closest training rows; choose k by cross-validation.",
    "Gradient boosting adds small trees one at a time, each fitted to the errors of the previous ones.",
    "Fit the scaler on the training split only, or information leaks from the test set.",
    "Logistic regression turns a score into a probability with the sigmoid.",
    "A random forest averages many deep trees, each grown on a bootstrap sample.",
    "PCA rotates the data onto the directions of largest variance.",
]
vec = TfidfVectorizer()
P = vec.fit_transform(passages)                      # one sparse vector per passage
index = NearestNeighbors(n_neighbors=2, metric='cosine').fit(P)

def retrieve(question):
    dist, idx = index.kneighbors(vec.transform([question]))
    for d, i in zip(dist[0], idx[0]):
        print(f"{1 - d:.2f}  {passages[i]}")

retrieve("How do I choose k in k-NN?")
0.46  k-NN predicts from the k closest training rows; choose k by cross-validation.
0.00  Gradient boosting adds small trees one at a time, each fitted to the errors of the previous ones.
The question becomes a vector, and kneighbors returns the passages whose vectors are closest by cosine: the NearestNeighbors of the k-NN lesson, over the TF-IDF vectors of the text representation lesson. The k-NN passage comes back with a cosine similarity of 0.46; the runner-up has 0.00, because it shares no word with the question, and in TF-IDF two texts without a common word are orthogonal. A RAG system does exactly this and then pastes the retrieved passages into the LLM's prompt, so the answer can quote your documents. Real systems use dense embeddings and an approximate index instead of TF-IDF and brute force; the simulation shows why.
Simulation: the same question, in other words. Ask the same thing without the words of the passage: "How many neighbors should vote?" Which passage comes back now, and why?
Solution
0.32  A random forest averages many deep trees, each grown on a bootstrap sample.
0.00  Gradient boosting adds small trees one at a time, each fitted to the errors of the previous ones.
The retriever now returns the random forest passage, with 0.32, only because it contains the word many. The k-NN passage, which answers the question, shares no word with it (neighbors and vote do not appear in it), so its similarity is 0. TF-IDF matches words, not meanings. That is why RAG systems retrieve with dense sentence embeddings, in which "neighbors that vote" lands near "the k closest training rows": the retriever is still a k-NN; only the vectors change. A RAG answer can be no better than the passages its k-NN retrieves.
Step 3 — the reward model is a logistic regression
Predict. In the data below, people's votes depend on whether an answer is correct and, a little, on whether it is polite, but not on its length. A logistic regression without intercept is fitted on the differences between the features of the two answers of each pair. Which weights do you expect it to find? Why can it do without an intercept?
from sklearn.linear_model import LogisticRegression

rng = np.random.default_rng(0)
n_pairs = 2000


def answers(n):
    # each answer described by three features
    return np.column_stack([rng.integers(0, 2, n),      # correct: 0 or 1
                            rng.random(n),              # polite: from 0 to 1
                            rng.random(n) * 5])         # length: from 0 to 5 hundred words


A, B = answers(n_pairs), answers(n_pairs)
w_people = np.array([3.0, 1.0, 0.0])                    # what people value: correctness, a bit of politeness, not length
p_A = 1 / (1 + np.exp(-(A - B) @ w_people))             # P(A preferred to B) = sigmoid(r_A - r_B)
prefers_A = (rng.random(n_pairs) < p_A).astype(int)     # one human vote per pair
print(f"{n_pairs} compared pairs, A preferred in {prefers_A.mean():.0%} of them")

reward = LogisticRegression(fit_intercept=False, C=np.inf).fit(A - B, prefers_A)
print("weights of the reward model:", reward.coef_[0].round(2))

best, worst = np.array([[1, 1.0, 1.0]]), np.array([[0, 0.0, 1.0]])
print(f"P(correct and polite beats wrong and rude) = {reward.predict_proba(best - worst)[0, 1]:.2f}")
2000 compared pairs, A preferred in 50% of them
weights of the reward model: [2.98 1.12 0.03]
P(correct and polite beats wrong and rude) = 0.98
The reward of an answer is a weighted sum of its features, \(r = w \cdot x\), and the probability that people prefer A to B is \(\sigma(r_A - r_B) = \sigma(w \cdot (x_A - x_B))\): a logistic regression on the difference of the two answers, fitted with cross-entropy (C=np.inf turns off the penalty, as in the logistic regression lesson). From 2,000 votes it recovers the weights people used, 2.98, 1.12 and 0.03 against 3, 1 and 0. No intercept is needed, and none should be there: swapping A and B must turn \(p\) into \(1 - p\), which \(\sigma(-z) = 1 - \sigma(z)\) guarantees only when there is no constant term (an intercept would favor whichever answer is shown first). In RLHF the features are not three columns but the internal representation of an LLM, and the reward model is a network with this same logistic output; the LLM is then tuned to produce answers the reward model scores high.
Simulation: voters who like long answers. Repeat the votes with the same pairs, but now with people who also like long answers: weights [3.0, 1.0, 0.8]. Refit the reward model. How likely is a short correct answer (50 words) to beat a long wrong one (500 words, equally polite), according to the fair reward model and according to the new one?
Solution
rng = np.random.default_rng(0)                          # same seed: the same pairs and the same random draws
A, B = answers(n_pairs), answers(n_pairs)
w_biased = np.array([3.0, 1.0, 0.8])
p_A = 1 / (1 + np.exp(-(A - B) @ w_biased))
prefers_A = (rng.random(n_pairs) < p_A).astype(int)
biased = LogisticRegression(fit_intercept=False, C=np.inf).fit(A - B, prefers_A)
print("weights, length-biased votes:", biased.coef_[0].round(2))
short_right, long_wrong = np.array([[1, 1.0, 0.5]]), np.array([[0, 1.0, 5.0]])
print(f"P(short and correct beats long and wrong): fair {reward.predict_proba(short_right - long_wrong)[0, 1]:.2f}"
      f" · biased {biased.predict_proba(short_right - long_wrong)[0, 1]:.2f}")
weights, length-biased votes: [3.02 1.03 0.76]
P(short and correct beats long and wrong): fair 0.95 · biased 0.40
The reward model learns the bias faithfully: a weight of 0.76 on length. With fair votes, the short correct answer wins with probability 0.95; with the biased votes, 0.40: the reward model now prefers the long wrong answer, because 450 extra words are worth more than being right. An LLM tuned to maximize that reward learns to write long. The logistic regression did nothing wrong: it measured the votes it was given. That is why the quality of the human comparisons (the data-centric chip of the map) and alignment itself are on the list of open problems.
Step 4 — route six requests
Predict. For each request below, decide with your partner: a foundation model, the classical stack, or both? Write one sentence of why, and how you would test the choice, before opening the solution.
| # | request |
|---|---|
| 1 | Sort 300 labeled customer e-mails, in Portuguese, into 5 intents; the system must be live next week |
| 2 | Score 50 million card transactions every night for fraud, on a tight budget |
| 3 | Approve or deny credit from a 60,000-row table; the regulator must see why each applicant was denied |
| 4 | Answer employees' questions about the company's 400-page HR manual |
| 5 | Predict the yield of a chemical process from a 600-row table of lab measurements |
| 6 | Flag fraudulent insurance claims from 30 numeric columns plus the free-text account of the accident |
Solution
| # | route | why | how to test it |
|---|---|---|---|
| 1 | foundation model | language, few labels, little time: a few-shot prompt, or embeddings of the e-mails plus a logistic regression trained on the 300 labels | hold out part of the 300 as a labeled test set; per-intent precision and recall |
| 2 | classical | a table, billions of scores a year, milliseconds each: gradient boosting or logistic regression | time-ordered validation; precision and recall at the chosen threshold, since fraud is rare |
| 3 | classical | tabular and regulated: logistic regression or boosting with SHAP, whose reasons can be shown | cross-validation, then one test; explanations checked by a person |
| 4 | foundation model, with RAG | the answers are in your documents: embed the manual's passages, retrieve the nearest ones (a k-NN) and put them in the prompt | a labeled set of questions with the passage that answers each: is it retrieved (recall at k)? is the answer right? |
| 5 | classical, with TabPFN as a challenger | a small table: a regularized model or boosting with cross-validation; at 600 rows a tabular foundation model is worth testing too | the same folds for every candidate, compared fold by fold |
| 6 | both | the text goes through a foundation model (embeddings or an extracted label) and becomes columns; boosting decides from all of them | the text features must be computed inside the cross-validation, like any other preprocessing, to avoid leakage |
Only one request out of six is purely a foundation-model job and one more needs both: most problems that reach a data team are still tables. Every row of the last column needs a labeled test set, whatever the route.
To close the fundamental part. In one sentence each: (1) name two pieces of this course that sit inside an LLM system, and where; (2) what separates feature extraction, fine-tuning and prompting? (3) Why does a prompt still need a labeled test set?
Your turn (fundamental)
At home:
- Three dashed chips. Pick three dashed chips on the map. For each, write what it builds on and in which lesson of this course you learned that.
- Dense retrieval. Redo step 2 with the sentence embeddings of the sentence embeddings lesson instead of TF-IDF (
NearestNeighbors(metric='cosine')works the same on dense vectors). Does "How many neighbors should vote?" now find the k-NN passage? - An intercept for the first answer. In step 3, make people slightly prefer whichever answer is shown first (add 0.5 to the score difference in
p_A) and fit the reward model withfit_intercept=True. What does the intercept learn?
Advanced approach
The fundamental part placed the frontier on the map and routed problems to the right tool. This part opens three of the frontier's boxes: LoRA, counted for a whole model, and why a thin slice of each matrix can be enough; TabPFN, the challenger of boosted trees on small tables, and how to test it; and the open problems. The code blocks are independent of those of the fundamental part.
This part follows one path in three stages, drawn below: 1. fine-tune a thin slice; 2. challenge the trees; 3. face the open problems. Each stage links to its section, and in the slides a strip at the bottom shows which stage you are in.
- Fine-tune a thin sliceLoRA counted layer by layer; why low rank is enough
- Challenge the treeswhy trees lead on tables; TabPFN; a fair test
- Face the open problemsreliability, evaluation, alignment, efficiency, governance
Advanced approach slides
Click the slides and use the ← → arrows to navigate; F opens full screen and Esc shows every slide. Open the slides in a new tab
6. LoRA: fine-tune a thin slice
Stage 1. A layer of a network computes \(h = Wx\), with \(W\) a matrix of \(d_{out} \times d_{in}\) pre-trained weights. Full fine-tuning learns a new matrix \(W + \Delta W\), with \(\Delta W\) free: \(d_{out} \cdot d_{in}\) numbers to train, for every matrix of the model. LoRA (low-rank adaptation; Hu et al., 2022) keeps \(W\) frozen and forces the update to be a product of two thin matrices:
Only \(B\) and \(A\) are trained: \(r\,(d_{in} + d_{out})\) numbers instead of \(d_{in}\, d_{out}\). \(A\) starts random and \(B\) starts at zero, so \(BA = 0\) and training starts exactly at the pre-trained model; Hu et al. also multiply \(BA\) by a constant \(\alpha / r\), so that changing \(r\) does not change the size of the update. After training, \(BA\) can be added into \(W\) once, and the adapted model costs nothing extra to run.
Counting a whole model
Section 2 counted one \(4096 \times 4096\) matrix. A whole model has hundreds of matrices of two shapes. The code counts them for a model with the published shape of Llama 2 7B (Touvron et al., 2023): 32 layers, each with four \(4096 \times 4096\) attention matrices (\(q\), \(k\), \(v\), \(o\)) and three MLP matrices between 4,096 and 11,008 units, plus the embeddings of a 32,000-token vocabulary:
d, d_ff, n_layers, vocab = 4096, 11008, 32, 32000      # the published shape of Llama 2 7B

# every weight matrix of one transformer layer, as (rows, columns)
layer = {'q': (d, d), 'k': (d, d), 'v': (d, d), 'o': (d, d),               # attention
         'gate': (d, d_ff), 'up': (d, d_ff), 'down': (d_ff, d)}             # MLP
per_layer = sum(r * c for r, c in layer.values()) + 2 * d                  # + two normalization vectors
total = n_layers * per_layer + 2 * vocab * d + d                           # + embeddings, output head, final norm
print(f"one layer {per_layer:,} · whole model {total:,}")


def lora(adapted, r):
    # LoRA trains B (rows x r) and A (r x columns) for each adapted matrix of each layer
    return n_layers * sum(r * (layer[m][0] + layer[m][1]) for m in adapted)


for adapted in (['q', 'v'], ['q', 'k', 'v', 'o'], list(layer)):
    n = lora(adapted, r=8)
    print(f"LoRA r=8 on {'+'.join(adapted):22s} {n:>11,} trained · {n / total:.3%} of the model")
one layer 202,383,360 · whole model 6,738,415,616
LoRA r=8 on q+v                      4,194,304 trained · 0.062% of the model
LoRA r=8 on q+k+v+o                  8,388,608 trained · 0.124% of the model
LoRA r=8 on q+k+v+o+gate+up+down    19,988,480 trained · 0.297% of the model
The model has 6,738,415,616 weights, the "7B" of its name; one layer holds 202,383,360 of them, two thirds in the MLP. Hu et al. adapted only \(q\) and \(v\), and found that enough on their tasks: at rank 8 that is 4,194,304 trained numbers, 0.062% of the model. Adapting every matrix of every layer still trains less than 0.3%.
The simulator walks through the same count, one piece of the model per step: one matrix, the attention of one layer, the whole layer, 32 layers, the embeddings, and finally the memory that training needs (the subject of lab step 5). Before stepping, predict: as the pieces add up, does the share that LoRA trains grow, shrink or stay the same? Change the rank and the adapted matrices and watch every count follow.
Why a thin slice can be enough
The product \(BA\) has rank at most \(r\): whatever training does, LoRA can only make updates of rank \(\le r\). It works when the update that fine-tuning needs is close to low rank. Aghajanyan et al. (2021) found that fine-tuning a pre-trained language model has a low intrinsic dimension: on some tasks, training a few hundred numbers, projected into the full weight space, reaches 90% of the performance of full fine-tuning, and Hu et al. (2022) built LoRA on the hypothesis that the weight updates have a low intrinsic rank, which their experiments supported: ranks as small as 1 to 8 were competitive with full fine-tuning on their benchmarks. It is an empirical fact about pre-trained models, not a law: lab step 6 shows what happens when the update is not low rank.
7. Tabular foundation models: TabPFN
Stage 2. The routing rule sends tables to the classical stack. This is the one place where a foundation model challenges that rule head on.
Why trees still lead on tables
Grinsztajn, Oyallon & Varoquaux (2022) benchmarked 45 tabular datasets of around 10,000 rows and found tree ensembles ahead of deep networks. They traced the gap to three properties of tables: the target functions are irregular, and networks are biased toward smooth functions; tables carry many uninformative columns, which hurt networks more than trees; and the columns have meanings of their own (age, income), so mixing them, as the first layer of a network does, throws away structure that a tree's one-column questions keep.
A forward pass instead of a fit
TabPFN (Hollmann et al., 2023, 2025) takes a different route. It is a prior-data fitted network (Müller et al., 2022): a transformer pre-trained, once and offline, on millions of synthetic datasets drawn from a broad family of random data-generating processes. Each pre-training example is a whole small table: the training rows with their labels and some test rows without them, and the target is the labels of the test rows. To use it on your table, you give it your training rows and your new rows as input, and it outputs the predictions in one forward pass: no gradient step on your data, no hyperparameter search. It is in-context learning, as in few-shot prompting, with a table in place of the prompt; Müller et al. showed that such a network approximates Bayesian prediction under the prior it was trained on.
On classification datasets of up to 10,000 rows, the 2025 version beat, in 2.8 seconds, an ensemble of the strongest baselines (boosted trees among them) tuned for 4 hours. The price is paid at prediction time: the whole training table is part of the input of every prediction, so the model is large and slow to run next to a fitted tree, and it was designed for small tables (the 2025 version targets up to 10,000 rows and 500 features). Above that size, and whenever latency matters, boosted trees remain the default.
Testing the challenger
Test the challenger the way you tested every model in this course: same folds, same metric, paired comparison, and at the size of your table. Who wins depends on the size: lab step 7 shows a regularized linear model beating gradient boosting on a 300-row sample of California housing and losing on every fold from 1,000 rows on. A benchmark result ("best up to 10,000 rows") is a claim about a range of sizes, measured on other people's tables; your validation is the only test that counts.
8. Open problems — where this field is going
Stage 3. The map has dashed chips because the field is not finished. These problems are open:
- Hallucination and reliability: fluent falsehoods. Calibration at frontier scale: a model should know when it does not know.
- Evaluation: benchmarks saturate within a year or two and leak into training data; honest measurement is an arms race (Validation, scaled up).
- Alignment and safety: making systems pursue the goals we intend; RLHF and its successors are partial answers. The simulation of lab step 3 showed a reward model faithfully learning a bias of its voters.
- Efficiency: distillation, quantization, small specialized models against giant generalists.
- Data provenance, bias and governance: the ethics questions of the ML landscape lesson, now industrialized and regulated (EU AI Act; in Brazil, the LGPD and the AI bill PL 2338/2023, approved by the Senate in December 2024 and sent to the Chamber of Deputies).
- Causality: prediction answers "what will happen"; decisions need "what happens if we act". Causal ML joins the two.
- Agents: models that plan, call tools and act. How to evaluate them and keep them safe is largely unsolved.
9. Summary: inside the frontier's tools
- LoRA trains \(B\) and \(A\), \(r\,(d_{in} + d_{out})\) numbers per adapted matrix, with \(W\) frozen: 0.062% of a 7-billion-parameter model at rank 8 on \(q\) and \(v\).
- It saves memory and storage more than compute: the frozen copy still has to be held, but each task is a small adapter.
- It works because fine-tuning updates are close to low rank in pre-trained models; an update that is not low rank cannot be captured by a thin slice.
- TabPFN predicts a small table in one forward pass of a transformer pre-trained on synthetic tables; boosted trees remain the default for larger tables and tight latency.
- A challenger is tested like any model: your table, your size, the same folds, fold by fold.
| tool | what it changes | what does not change |
|---|---|---|
| LoRA | trains under 0.3% of the weights; one small adapter per task | you still need labels and a test set |
| TabPFN | no training and no tuning on small tables | the comparison on your folds decides |
| foundation models in general | language and perception with few labels | leakage, calibration and bias, now at scale |
Advanced lab — count, compress, test
The problem. Your team wants to fine-tune a 7-billion-parameter model for a customer-service task, and someone proposes replacing the boosted trees of a small tabular model with a tabular foundation model. Before the meeting, you check three things with code: what fine-tuning costs in memory, when a low-rank update is enough, and how much the winner of a comparison depends on the size of the table.
How to do this lab in class (about 30 min, in pairs)
- Same notebook (or a new one): step 5 uses
totalandlorafrom the code block of section 6; run that block first. Steps 6 and 7 are independent. - Every step starts with a Predict: answer it before running.
- Step 7 fits 50 models; it takes about two minutes.
- Suggested pace: step 5 and its simulation in 10 min; step 6 and its simulation in 10 min; step 7 in 10 min.
Step 5 — what fine-tuning costs in memory
Predict. LoRA trains 0.062% of the numbers of the model. Does it need 0.062% of the memory of full fine-tuning? Much more? Why?
GB = 1e9
trained_bytes = 16          # mixed-precision Adam: 16-bit weight and gradient, 32-bit master copy and two moments
frozen_bytes = 2            # a frozen weight is only read: one 16-bit copy

full = total * trained_bytes
n_lora = lora(['q', 'v'], r=8)
with_lora = total * frozen_bytes + n_lora * trained_bytes
print(f"full fine-tuning: {full / GB:6.1f} GB · LoRA r=8 on q+v: {with_lora / GB:5.1f} GB")
print(f"saved per task:   {total * 2 / GB:6.1f} GB (a full copy) · {n_lora * 2 / 1e6:.1f} MB (an adapter)")
full fine-tuning:  107.8 GB · LoRA r=8 on q+v:  13.5 GB
saved per task:     13.5 GB (a full copy) · 8.4 MB (an adapter)
Training with the Adam optimizer in mixed precision keeps 16 bytes per trained number (the accounting of Rajbhandari et al., 2020; activations come on top and depend on the batch). Full fine-tuning needs 107.8 GB, more than a single 80 GB accelerator holds. With LoRA, 13.5 GB: 8 times less, not 1,600 times, because the frozen 16-bit copy of the model still has to be in memory, and now it is almost all of it. The other saving is storage: each new task is an adapter of 8.4 MB instead of a 13.5 GB copy of the model, so one base model can serve hundreds of tasks.
Simulation: shrink the frozen part. QLoRA (Dettmers et al., 2023) stores the frozen weights in 4 bits (half a byte) and trains LoRA on top. How much memory does that need? And how much does the rank \(r\) change the memory, from 1 to 64?
Solution
four_bit = total * 0.5 + n_lora * trained_bytes
print(f"QLoRA (frozen weights in 4 bits): {four_bit / GB:.1f} GB")
for r in (1, 4, 8, 16, 64):
    print(f"r={r:<3d} {lora(['q', 'v'], r):>11,} trained · {(total * frozen_bytes + lora(['q', 'v'], r) * trained_bytes) / GB:.2f} GB")
QLoRA (frozen weights in 4 bits): 3.4 GB
r=1       524,288 trained · 13.49 GB
r=4     2,097,152 trained · 13.51 GB
r=8     4,194,304 trained · 13.54 GB
r=16    8,388,608 trained · 13.61 GB
r=64   33,554,432 trained · 14.01 GB
In 4 bits the frozen model takes 3.4 GB: a 7-billion-parameter model can be fine-tuned on a single consumer graphics card. The rank barely matters for memory: from \(r = 1\) to \(r = 64\) the trained numbers grow 64 times, and the memory goes from 13.49 to 14.01 GB. Once the update is a thin slice, what costs memory is the frozen model, which is why the next saving came from compressing it.
Step 6 — when is a thin slice enough?
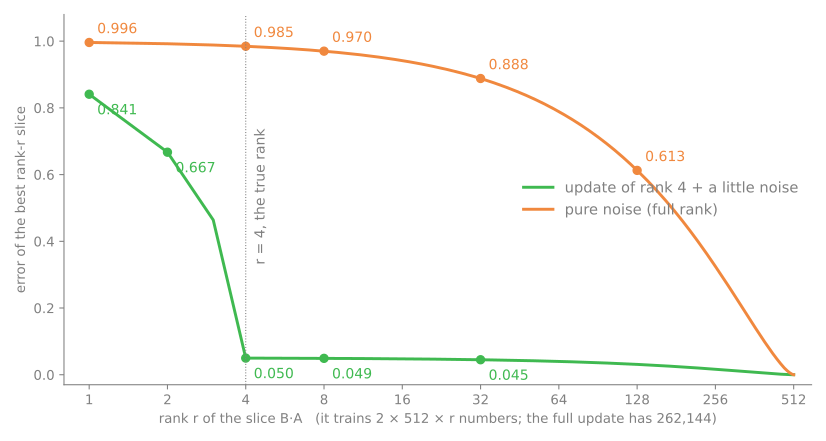
Predict. The update delta below has rank 4, plus a little noise. The function measures the best that any \(B \cdot A\) of rank \(r\) can do (the truncated SVD, by the Eckart–Young theorem), as the size of what is left over relative to the size of the update. How does that error change from \(r = 1\) to \(r = 32\)?
import numpy as np

rng = np.random.default_rng(0)
d = 512
# an update that really has rank 4, plus a little noise
delta = rng.normal(size=(d, 4)) @ rng.normal(size=(4, d)) + 0.1 * rng.normal(size=(d, d))


def best_rank_r_error(M, r):
    # the best any B (d x r) times A (r x d) can do: keep the r largest singular values (Eckart-Young)
    U, s, Vt = np.linalg.svd(M)
    approx = (U[:, :r] * s[:r]) @ Vt[:r]
    return np.linalg.norm(M - approx) / np.linalg.norm(M)


print(f"full update: {d * d:,} numbers")
for r in (1, 2, 4, 8, 32):
    print(f"r={r:<3d} {2 * d * r:>7,} numbers · error {best_rank_r_error(delta, r):.3f}")
full update: 262,144 numbers
r=1     1,024 numbers · error 0.841
r=2     2,048 numbers · error 0.667
r=4     4,096 numbers · error 0.050
r=8     8,192 numbers · error 0.049
r=32   32,768 numbers · error 0.045
The error falls slowly at \(r = 1\) and 2, then drops to 0.050 at \(r = 4\), the true rank, and stops there: what is left (0.049, 0.045) is the noise, which no low-rank slice can capture and none needs to. With 4,096 numbers instead of 262,144 (1.6%), the slice reproduces the update up to the noise. A larger \(r\) only buys more numbers. This is the situation LoRA bets on.
Simulation: an update with no structure. Replace delta by a matrix of pure noise, rng.normal(size=(d, d)), which has full rank. What is the error now at \(r = 1, 4, 8, 32\) and \(128\)?
Solution
noise = rng.normal(size=(d, d))
for r in (1, 4, 8, 32, 128):
    print(f"r={r:<3d} {2 * d * r:>7,} numbers · error {best_rank_r_error(noise, r):.3f}")
r=1     1,024 numbers · error 0.996
r=4     4,096 numbers · error 0.985
r=8     8,192 numbers · error 0.970
r=32   32,768 numbers · error 0.888
r=128 131,072 numbers · error 0.613
Now there is no structure to exploit: rank 8 leaves 97% of the update, and even rank 128, with half as many numbers as the full matrix (131,072 against 262,144), leaves 61%. A thin slice can only learn an update that is close to low rank. LoRA works on large language models because the updates that fine-tuning needs there are, empirically, close to low rank; on a task far from what the model was pre-trained on, a small \(r\) may not be enough.
The figure draws both errors for every rank from 1 to 512, with the values of this step marked (figure script):
Step 7 — who wins depends on the size of the table
Predict. On samples of 100 to 10,000 rows of California housing, a regularized linear model (RidgeCV, with imputation and scaling) is compared with gradient boosting on the same five folds. At 100 rows, which do you expect to win? And at 10,000?
import pandas as pd
from sklearn.ensemble import HistGradientBoostingRegressor
from sklearn.impute import SimpleImputer
from sklearn.linear_model import RidgeCV
from sklearn.model_selection import KFold, cross_val_score
from sklearn.pipeline import make_pipeline
from sklearn.preprocessing import StandardScaler

housing = pd.read_csv('https://raw.githubusercontent.com/hsandmann/biblio/refs/heads/main/ml/aula02/housing.csv')
X_all = housing.drop(columns=['median_house_value', 'ocean_proximity'])
y_all = housing['median_house_value']
print(X_all.shape)

linear = make_pipeline(SimpleImputer(strategy='median'), StandardScaler(), RidgeCV())
boosting = HistGradientBoostingRegressor(random_state=0)
cv = KFold(n_splits=5, shuffle=True, random_state=0)

for n in (100, 300, 1000, 3000, 10000):
    sample = X_all.sample(n, random_state=0)
    X_n, y_n = sample, y_all.loc[sample.index]
    rmse = {}
    for name, model in (('linear', linear), ('boosting', boosting)):
        rmse[name] = -cross_val_score(model, X_n, y_n, cv=cv, scoring='neg_root_mean_squared_error')
    wins = (rmse['boosting'] < rmse['linear']).sum()
    print(f"n={n:>6,}  linear {rmse['linear'].mean():>7,.0f}  boosting {rmse['boosting'].mean():>7,.0f}"
          f"  boosting wins {wins} of 5 folds")
(20640, 8)
n=   100  linear  60,842  boosting  71,432  boosting wins 1 of 5 folds
n=   300  linear  64,830  boosting  71,952  boosting wins 0 of 5 folds
n= 1,000  linear  69,439  boosting  58,184  boosting wins 5 of 5 folds
n= 3,000  linear  69,139  boosting  53,752  boosting wins 5 of 5 folds
n=10,000  linear  70,025  boosting  49,547  boosting wins 5 of 5 folds
The winner flips between 300 and 1,000 rows. At 100 and 300 rows the linear model has the lower RMSE (in dollars of median house value) and boosting wins at most one fold: with so few rows, a flexible model has more variance than signal to fit. From 1,000 rows on, boosting wins every fold, and its error keeps falling (58,184 → 49,547) while the linear model's stays near 70,000, the limit of a straight line. The bias–variance trade-off decides, and the size of the table moves it. This is why the claim of a tabular foundation model is a claim about a range of sizes, and why the only test that settles it is the one on your table, at your size, on the same folds, fold by fold.
To close the lesson. In one sentence each: (1) why does LoRA cut the memory of fine-tuning 8 times and not 1,600 times? (2) When would a rank-8 update fail to adapt a model? (3) How would you decide between TabPFN and boosted trees for a 5,000-row table?
Your turn (advanced)
At home, with more time:
- LoRA everywhere. With the code of section 6 and the memory accounting of step 5, how many numbers does LoRA train at \(r = 16\) on all seven matrices of each layer, and how much memory does it need, with the frozen weights in 16 bits and in 4 bits?
- A third contender. In step 7, add the whole table (
n = 20640) and aRandomForestRegressor(n_estimators=200, random_state=0, n_jobs=-1). At which sizes does each model win, fold by fold? - Read the challenger. Read Hollmann et al. (2025) in the references and list the kinds of tables TabPFN was not designed for. For each, say which model of this course you would use instead.
Where to go from here
- Deep learning, in depth: the Insper course Artificial Neural Networks and Deep Learning (CNNs, transformers, generative models); Prince, Understanding Deep Learning (2023, free online).
- The probabilistic view: Murphy, Probabilistic Machine Learning (2022, free online), for the Bayesian models, Gaussian processes and uncertainty this course only touched.
- LLMs, hands on: the Hugging Face courses (tokenizers, fine-tuning, RAG); Karpathy's Neural Networks: Zero to Hero, which builds a GPT from scratch.
- Reading papers: pick a dashed chip on the map, read its classic paper, then find a recent paper that cites it. The map's links are the starting points.
The course thesis, one last time
Every "new" idea you will meet is a composition of things you now understand: losses, gradients, regularization, embeddings, neighbors, ensembles, honest validation. The frontier moves; the foundations compound. Learn the parts, and no whole will be a black box.
References
The map carries one to three references per technique. These are the ones the text of this lesson relies on.
- Sutton, R. "The Bitter Lesson." Essay (2019). Link
- Vaswani, A. et al. "Attention Is All You Need." NeurIPS (2017). arXiv:1706.03762
- Howard, J.; Ruder, S. "Universal Language Model Fine-tuning for Text Classification." ACL (2018). arXiv:1801.06146
- Devlin, J.; Chang, M.-W.; Lee, K.; Toutanova, K. "BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding." NAACL-HLT (2019). arXiv:1810.04805
- Kaplan, J. et al. "Scaling Laws for Neural Language Models." arXiv (2020). arXiv:2001.08361
- Brown, T. B. et al. "Language Models are Few-Shot Learners." NeurIPS (2020) — GPT-3. arXiv:2005.14165
- Lewis, P. et al. "Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks." NeurIPS (2020). arXiv:2005.11401
- Rajbhandari, S.; Rasley, J.; Ruwase, O.; He, Y. "ZeRO: Memory Optimizations Toward Training Trillion Parameter Models." SC20 (2020) — the 16 bytes per trained parameter of mixed-precision Adam. arXiv:1910.02054
- Aghajanyan, A.; Gupta, S.; Zettlemoyer, L. "Intrinsic Dimensionality Explains the Effectiveness of Language Model Fine-Tuning." ACL (2021). arXiv:2012.13255
- Bommasani, R. et al. "On the Opportunities and Risks of Foundation Models." arXiv (2021). arXiv:2108.07258
- Hu, E. J. et al. "LoRA: Low-Rank Adaptation of Large Language Models." ICLR (2022). arXiv:2106.09685
- Müller, S.; Hollmann, N.; Pineda Arango, S.; Grabocka, J.; Hutter, F. "Transformers Can Do Bayesian Inference." ICLR (2022) — prior-data fitted networks. arXiv:2112.10510
- Ouyang, L. et al. "Training Language Models to Follow Instructions with Human Feedback." NeurIPS (2022) — RLHF. arXiv:2203.02155
- Grinsztajn, L.; Oyallon, E.; Varoquaux, G. "Why Do Tree-Based Models Still Outperform Deep Learning on Typical Tabular Data?" NeurIPS Datasets and Benchmarks (2022). arXiv:2207.08815
- Hollmann, N.; Müller, S.; Eggensperger, K.; Hutter, F. "TabPFN: A Transformer That Solves Small Tabular Classification Problems in a Second." ICLR (2023). arXiv:2207.01848
- Touvron, H. et al. "Llama 2: Open Foundation and Fine-Tuned Chat Models." arXiv (2023) — the shape counted in section 6. arXiv:2307.09288
- Dettmers, T.; Pagnoni, A.; Holtzman, A.; Zettlemoyer, L. "QLoRA: Efficient Finetuning of Quantized LLMs." NeurIPS (2023). arXiv:2305.14314
- Sainz, O. et al. "NLP Evaluation in Trouble: On the Need to Measure LLM Data Contamination for each Benchmark." Findings of EMNLP (2023). arXiv:2310.18018
- Hollmann, N. et al. "Accurate Predictions on Small Data with a Tabular Foundation Model." Nature 637 (2025): 319–326. DOI
- Regulation (EU) 2024/1689 (Artificial Intelligence Act). Official Journal of the European Union (2024). EUR-Lex
Quiz
The quiz covers the fundamental approach.