The ML Landscape
Before diving into algorithms, we need a map: what kinds of learning exist, what a real ML project looks like from end to end, and what it means for a model to generalize.
This lesson draws that map with almost no algorithms. The models that appear — polynomials, a lookup table, a straight line, nearest neighbors, a small tree — are used as black boxes; each one has its own lesson later. What matters here is what they show: an error measured on the training data says little, no model wins on every problem, and a model learns whatever its data contain, including the mistakes of the past. Every number quoted comes from the code blocks or from the figure scripts next to this page.
How this lesson is organized
The lesson has two approaches. Each has slides, text and a lab to do in class; the quiz at the end covers the fundamental one. Start with the fundamental approach: the advanced one builds on it.
| Fundamental approach | Advanced approach | |
|---|---|---|
| question | What kind of learning is a problem, which steps does a project take, and how do you know a model works on data it has never seen? | How does a wish become an ML problem, why does no model win everywhere, and what goes wrong when a model's decisions reach people? |
| content | supervised, unsupervised and reinforcement learning; regression and classification; the six steps of the project loop; training and new-data error; underfitting and overfitting; the golden rule | framing a problem (target, moment, metric, baseline), the expected loss, no free lunch, bias in the data and proxies, fairness, privacy, transparency, feedback loops |
| in-class lab | the shape of the error, steps 1 to 4 | no free lunch, a biased past and a loop that feeds itself, steps 5 to 7 |
| by the end, you can | name the paradigm and the task of a problem from its data; place a task in the project loop; tell underfitting from overfitting by the two errors; explain why a model is never judged on its training data | frame a problem before touching data; explain why the course compares several families; spot a proxy that carries a bias; recognize a model that writes its own training data |
Both labs run from this page: there is no notebook to download. Open a blank Colab notebook (it already has NumPy, pandas and scikit-learn), paste each code block into its own cell and run them in order: the fundamental part runs from step 1 to 4, the advanced part from step 5 to 7.
Fundamental approach
One question drives this part: given a problem, what kind of learning is it, which steps will the project take, and how will you know the model works on data it has never seen? The first two answers are a vocabulary and a loop; the third is the central problem of the whole course, and the lab measures it with numbers.
This part follows one path in three stages, drawn below: 1. kinds of learning, sorted by the feedback the learner gets; 2. the project loop, the steps of a real project from the question to a deployed model; 3. generalization, what makes a model good on data it has never seen. Each stage links to its section, and in the slides a strip at the bottom shows which stage you are in.
- Kinds of learningsupervised, unsupervised, reinforcement: by the feedback
- The project loopframe, get data, prepare, train, evaluate, deploy: a loop
- Generalizationtraining and new data; underfitting and overfitting
Fundamental approach slides
Click the slides and use the ← → arrows to navigate; F opens full screen and Esc shows every slide. Open the slides in a new tab
1. Learning paradigms
Stage 1. Machine learning problems are classified by the kind of feedback available to the learner.
Supervised learning
The dataset contains inputs \(x\) and the desired outputs \(y\) (labels). The goal is to learn a function \(f\) such that \(f(x) \approx y\) on new data.
- Regression — \(y\) is continuous: predicting house prices, energy demand, a patient's length of stay (the regression lessons).
- Classification — \(y\) is categorical: spam/ham, tumor benign/malignant, which digit is in the image (the classification lessons, trees and ensembles).
Unsupervised learning
Only inputs \(x\) — no labels. The goal is to discover structure:
- Clustering — group similar observations, e.g. customer segments (Clustering);
- Dimensionality reduction — compress many features into few informative ones (PCA, t-SNE, UMAP);
- Topic modeling — discover themes in a collection of documents (BERTopic).
Reinforcement learning
An agent interacts with an environment, receives rewards, and learns a policy that maximizes long-term reward — the paradigm behind game-playing systems (AlphaGo) and robotic control. It is out of scope for this course, but you should recognize it on the map.
In between
Real projects often mix paradigms: semi-supervised learning (few labels, many unlabeled examples), self-supervised learning (labels manufactured from the data itself — how foundation models are pre-trained), and weak supervision (noisy, programmatic labels).
2. The ML workflow
Stage 2. A model is a small part of a larger, iterative process. This course is organized around this loop:
Two practical truths about this diagram:
- Most of the work is in steps 2–3. Practitioners routinely report spending the majority of their time understanding and preparing data, not fitting models.
- The loop never ends. Deployed models decay as the world changes (drift); monitoring and retraining are part of the job, not an afterthought.
The first box, frame the problem, looks like the easiest and is where a project is most often doomed without anyone noticing; the advanced approach gives it its own section.
3. Generalization: the central problem
Stage 3. A model that memorizes its training data perfectly can still be useless. What matters is performance on data it has never seen.
- Underfitting: the model is too simple to capture the pattern — poor performance even on training data.
- Overfitting: the model captures noise as if it were signal — excellent on training data, poor on new data.
Three models, by eye
The figure shows both failures and the balance between them on the data of the fundamental lab: 15 training points drawn around a smooth curve (dashed), and 1,000 new points from the same process that the models never see. Each panel fits a polynomial to the 15 points; the error under it is the mean squared error (MSE), the average of the squared vertical distances between the points and the curve (figure script):
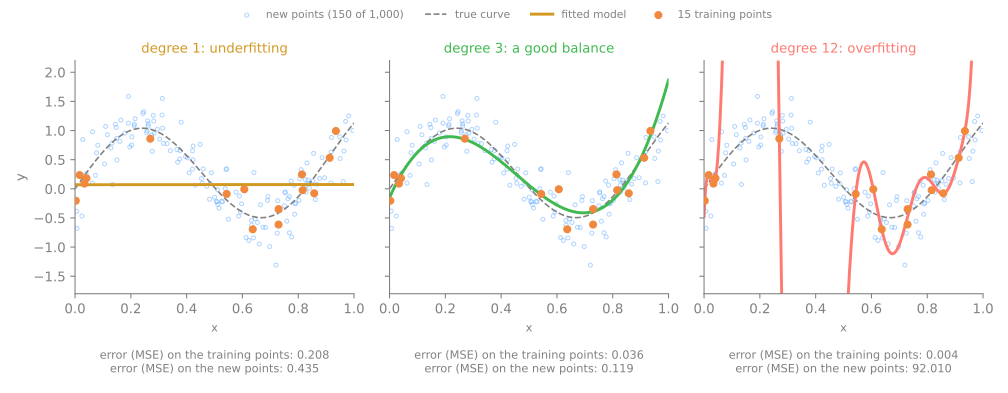
Read the training errors from left to right: 0.208, 0.036, 0.004, always falling. The errors on new points tell another story: 0.435, 0.119, then 92.010. The degree-12 curve is the best on the points it saw and by far the worst on the points it did not.
Try it: the generalization simulator
In the simulator below, move the polynomial degree from 1 to 15 and watch both errors: where is the model underfitting, and where does it start overfitting? Then press more data and slide the degree up again.
The training error only goes down as the model gets more flexible; the test error is what tells you when it has started memorizing noise. With more data the same flexible model has much less room to overfit.
The golden rule
In the lab and in the simulator the "new points" come from a generator we wrote, so we can draw as many as we like. A real project has no such generator: the only data that can play the role of the future is data you set aside and never train on. Everything in the lessons on regularization, cross-validation and model selection — train/test splits, cross-validation, regularization, the bias–variance trade-off — exists to manage this tension. For now, keep one rule:
The golden rule
Never evaluate a model on data it was trained on. Test data must simulate the future: unseen, untouched, used once.
4. Summary: the map in five lines
- Paradigms are sorted by feedback: labels (supervised), none (unsupervised), rewards (reinforcement).
- In supervised learning the type of \(y\) names the task: a number is regression, a category is classification.
- A project is a loop — frame, get data, prepare, train, evaluate, deploy — and most of the work is in the data.
- Read two errors, never one: both high is underfitting; training low and new-data high is overfitting.
- The training error cannot judge a model: only data the model never saw can, which is why the test set is locked away.
| what you see | what is happening | what to do |
|---|---|---|
| training and new-data errors both high and close | underfitting: the model is too simple | a more flexible model, better features |
| training error tiny, new-data error much larger | overfitting: it memorized the noise | a simpler model, more data |
| a score near 100% measured on the training rows | nothing yet: it is not evidence | measure on data the model never saw |
| a deployed model slowly getting worse | drift: the world changed | monitor and retrain |
Fundamental lab — the shape of the error
The problem. You will build a small world where you know the truth: points drawn around a smooth curve, plus noise. In it you can do something a real project never can, draw as many new points from the future as you like, and so watch what usually stays hidden: how a model does on data it has never seen. Then you will fit models of growing flexibility and find, with numbers, the underfitting, the overfitting and the balance of the figure in section 3.
How to do this lab in class (about 30 min, in pairs)
- Open a blank Colab notebook (File → New notebook). There is nothing to download or install: Colab runs in the browser and already has NumPy and scikit-learn. Paste each code block of this page into its own cell and run the cells in order, in a single session.
- This lab is steps 1 to 4. The advanced lab continues in the same notebook, from step 5.
- Every step starts with a Predict: answer it with your partner before running the cell. Getting the prediction wrong is what makes the result memorable.
- After running, compare with the output and the reading on this page. Every output here is exactly what the code prints.
- The Simulations ask you to write a small Python experiment: change one input and watch what happens to the output. No hand calculations. The solution is collapsed right below: try before opening it.
- Suggested pace: steps 1 and 2 in 8 min; step 3 and the first simulation in 10 min; step 4 and the second simulation in 12 min.
Step 1 — a world you control
Predict. The points are the curve plus noise with a standard deviation of 0.3. Could a perfect model, one that found the curve exactly, get the error on new points down to zero? Why not?
import numpy as np

def true_curve(x):
    return 0.9 * np.sin(2.2 * np.pi * x) + 0.6 * x

def draw(n, seed):
    rng = np.random.default_rng(seed)
    x = rng.uniform(0, 1, n)
    y = true_curve(x) + rng.normal(0, 0.3, n)        # the curve plus noise
    return x, y

x_train, y_train = draw(15, seed=0)                  # what the model learns from
x_new, y_new = draw(1000, seed=1)                    # the future: never shown to the model
print(len(x_train), 'training points ·', len(x_new), 'new points')
print('first three training points:', ', '.join(f'({a:.2f}, {b:.2f})' for a, b in zip(x_train[:3], y_train[:3])))
print('noise variance, the floor of the error on new points:', 0.3 ** 2)
15 training points · 1000 new points
first three training points: (0.64, -0.69), (0.27, 0.86), (0.04, 0.18)
noise variance, the floor of the error on new points: 0.09
Fifteen points to learn from and a thousand to judge with. The noise is part of every new point, and no model can predict it: even the true curve itself would miss each new point by the noise, and its mean squared error would be the noise variance, \(0.3^2 = 0.09\). That is the floor, the green "noise level" line of the simulator in section 3. In a real project nobody hands you draw; here it lets you see the error on the future directly.
Step 2 — three models, by eye
Predict. Polynomials of degree 1, 3 and 12 are fitted to the same 15 points. Rank them by their training error. Will the ranking by the error on new points be the same?
from numpy.polynomial import Polynomial

def mse(model, x, y):
    return np.mean((y - model(x)) ** 2)              # mean squared error

for degree in [1, 3, 12]:
    model = Polynomial.fit(x_train, y_train, degree)
    print(f"degree {degree:2d}: train {mse(model, x_train, y_train):.3f} · new {mse(model, x_new, y_new):.3f}")
degree  1: train 0.208 · new 0.435
degree  3: train 0.036 · new 0.119
degree 12: train 0.004 · new 92.010
These are the three panels of the figure in section 3. By training error the order is 12, 3, 1: the more flexible, the better. By error on new points it is 3, 1, 12, and the degree-12 polynomial is not a little worse, it is 92.010 against 0.119. The two rankings disagree, and only the second one describes what the model will do once deployed.
Step 3 — the whole curve
Predict. Now every degree from 0 to 14. Before running, sketch the two errors against the degree. Which one only falls? Where does the other have its minimum?
print('degree   train            new')
for degree in range(15):
    model = Polynomial.fit(x_train, y_train, degree)
    print(f"{degree:6d} {mse(model, x_train, y_train):7.3f} {mse(model, x_new, y_new):14,.3f}")
degree   train            new
     0   0.208          0.434
     1   0.208          0.435
     2   0.173          0.514
     3   0.036          0.119
     4   0.036          0.118
     5   0.035          0.111
     6   0.035          0.107
     7   0.028          0.514
     8   0.028          0.513
     9   0.023          1.765
    10   0.007         25.078
    11   0.006         83.926
    12   0.004         92.010
    13   0.002     79,229.911
    14   0.000 455,507,179.027
The training column never goes up: each extra degree can only bend the curve closer to the 15 points, and at degree 14 there are 15 coefficients for 15 points, so the curve passes through all of them and the training error is 0.000. The new-data column has the U shape of the simulator. Degrees 0 to 2 underfit (0.43 to 0.51, both errors high); degrees 3 to 6 sit between 0.107 and 0.119, close to the 0.09 floor; from degree 7 on, overfitting takes over, and at degree 14 the curve swings so wildly between the training points that its error on new ones is in the hundreds of millions. Degree 0, a horizontal line at the training mean, is the simplest model of all: it is the baseline that any model has to beat.
Simulation: more data. Draw 100 training points instead of 15 (draw(100, seed=0), same x_new and y_new) and refit degrees 1, 3, 5, 8, 12 and 14. Does the degree-14 polynomial still blow up on new points?
Solution
x_big, y_big = draw(100, seed=0)
for degree in [1, 3, 5, 8, 12, 14]:
    model = Polynomial.fit(x_big, y_big, degree)
    print(f"degree {degree:2d}, 100 points: train {mse(model, x_big, y_big):.3f} · new {mse(model, x_new, y_new):.3f}")
degree  1, 100 points: train 0.392 · new 0.327
degree  3, 100 points: train 0.092 · new 0.114
degree  5, 100 points: train 0.079 · new 0.104
degree  8, 100 points: train 0.076 · new 0.109
degree 12, 100 points: train 0.075 · new 0.111
degree 14, 100 points: train 0.074 · new 0.114
With 100 points the degree-14 polynomial scores 0.114 on new points, the same as degree 3, instead of 455 million. Its 15 coefficients can no longer pass through every point, so it has to follow the trend, and the noise of a hundred points mostly averages out. Notice also that the training errors are now close to the 0.09 floor and close to the new-data errors: with this much data, the training error stops lying. "Too flexible" is always relative to how much data you have.
Step 4 — a model that memorizes
Predict. The simplest possible "model" stores the training points and answers, for any \(x\), the \(y\) of the closest training point. What will its training error be? On new points, will it beat the degree-3 polynomial?
def memorizer(x_seen, y_seen):
    def model(x):
        nearest = np.abs(x[:, None] - x_seen[None, :]).argmin(axis=1)    # index of the closest seen x
        return y_seen[nearest]
    return model

memo = memorizer(x_train, y_train)
cubic = Polynomial.fit(x_train, y_train, 3)
print(f"memorizer: train {mse(memo, x_train, y_train):.3f} · new {mse(memo, x_new, y_new):.3f}")
print(f"degree 3:  train {mse(cubic, x_train, y_train):.3f} · new {mse(cubic, x_new, y_new):.3f}")
On its training points the memorizer is perfect by construction: the closest training point to a training point is itself. On new points it scores 0.175, worse than the degree-3 polynomial, because each answer carries the noise of the one point it copied. A perfect training score is what memorizing looks like, and it is exactly why the golden rule exists: had you judged these two models on their training points, you would have picked the worse one.
Simulation: nothing to learn. Shuffle the training labels (np.random.default_rng(0).permutation(y_train)), so that each \(y\) lands on a random \(x\) and no pattern is left, and build a memorizer on them. What is its training error now? And on new points, compare it with the 0.434 of degree 0 in step 3, the model that always answers the training mean.
Solution
y_random = np.random.default_rng(0).permutation(y_train)      # same y values, shuffled: no pattern left
memo_random = memorizer(x_train, y_random)
print(f"memorizer, shuffled y: train {mse(memo_random, x_train, y_random):.3f} · new {mse(memo_random, x_new, y_new):.3f}")
With random labels there is nothing to learn, and the training error is still 0.000: a memorizer is perfect on its training data with signal or without. On new points it scores 0.717, far worse than the 0.434 of simply answering the mean. The training error of a model flexible enough to memorize says nothing at all; only new data tells the two cases apart.
To close the fundamental part. In one sentence each: (1) what does the training error tell you about a model, and what can it not tell you? (2) Why did 100 points tame the degree-14 polynomial? (3) In the terms of section 1, which paradigm and which task is this lab?
Your turn (fundamental)
At home:
- Real data has no generator. Draw 30 points with
draw(30, seed=2), split them withtrain_test_split(x, y, test_size=0.5, random_state=0)(fromsklearn.model_selection) and redo step 3 with the test half playing the role of the new points. Do the two columns keep their shape? Why is the test column noisier than with 1,000 new points? - Name the paradigm. For each case, give the paradigm and, if supervised, the task: (a) tomorrow's electricity demand of a city, from five years of hourly demand; (b) grouping songs by their audio features, with no genres given; (c) flagging fraudulent card transactions, from past transactions marked by analysts; (d) a robot vacuum that learns a route from a score it gets at the end of each run.
- A quieter world. Change the noise in
drawfrom 0.3 to 0.1 and rerun steps 1 to 3. How low does the new-data error go now, and does the overfitting start at a higher or a lower degree?
Advanced approach
The fundamental part drew the map and found its central problem: a model must work on data it has never seen. This part asks what the map leaves out: how a vague wish becomes a problem a model can solve, why no model wins on every problem, and what goes wrong when a model's decisions reach people. The code blocks continue those of the fundamental lab.
This part follows one path in four stages, drawn below: 1. frame the problem; 2. no model wins everywhere; 3. bias in the data; 4. feedback loops. Each stage links to its section, and in the slides a strip at the bottom shows which stage you are in.
- Frame the problemtarget, moment, metric, baseline
- No model wins everywherethe expected loss; no free lunch
- Bias in the dataa model learns the past; proxies
- Feedback loopsa model that decides what it will see
Advanced approach slides
Click the slides and use the ← → arrows to navigate; F opens full screen and Esc shows every slide. Open the slides in a new tab
5. Framing a problem: target, moment, metric, baseline
Stage 1. "Reduce the number of patients who miss their appointments" is a wish, not an ML problem. The first box of the loop turns it into one by answering four questions, before any data is touched:
| question | what it fixes | the clinic, for example |
|---|---|---|
| target | what exactly is predicted, and so the task | did the patient miss the appointment: yes or no — classification |
| moment | when the prediction is made, and so which features are allowed | 48 hours before: age, past absences, days since booking; not a cancellation call made the day before, which nobody knows yet |
| metric | how success is measured, in the terms of whoever pays for the errors | a missed absence costs an empty slot, a false alarm costs one phone call: count the absences caught with the calls the staff can make |
| baseline | what the simplest reasonable answer scores | "nobody misses"; or, in regression, the training mean (degree 0 in step 3, DummyRegressor in step 5) |
Each question protects against a different failure. A vague target produces a model that answers the wrong question well. A wrong moment is leakage: a feature that is only known after the fact makes the model look excellent in the lab and useless in production (the preprocessing and pipelines lessons return to it). A metric chosen for convenience optimizes something nobody cares about (the classification metrics lesson is about choosing it). And without a baseline there is no way to tell whether 0.80 is impressive or worse than doing nothing. Sometimes the honest answer to the four questions is that no model is needed: a rule written by a person is cheaper to build, to explain and to fix.
6. The goal, written down
Stage 2. The central problem of the fundamental part fits in one line:
Each symbol names something from the lab. \(f\) is the model; \((x, y)\) is a new example, drawn from \(\mathcal{D}\), the distribution of the data the model will meet once deployed (in the lab, the function draw); \(L\) is the loss, the price of one wrong answer (in the lab, the squared error \((y - f(x))^2\)); and \(\mathbb{E}\) is the average over all such new examples. The "new" column of step 3 is this average estimated with 1,000 draws, which was possible only because we had draw. With real data, a test set plays that role, and it estimates the expected loss honestly only if the model never saw it. Two things can break the estimate in production: a test set that leaked into training, and a \(\mathcal{D}\) that changes after deployment (the drift of the loop).
7. No free lunch
The No Free Lunch theorem (Wolpert, 1996) says that averaged over all possible problems, no learning algorithm is better than any other. In practice this means: there is no universally best model — you must try several families and validate. That is why this course teaches a portfolio (linear models, neighbors, kernels, trees, ensembles, networks) rather than a single silver bullet.
The figure shows the idea on two small worlds, the same that step 5 of the lab measures: a straight one (\(y = 2x\) plus noise) and the wiggly curve of the fundamental lab. A straight line and a 5-nearest-neighbors model (it answers the average \(y\) of the 5 closest training points) are fitted to 30 points of each (figure script):
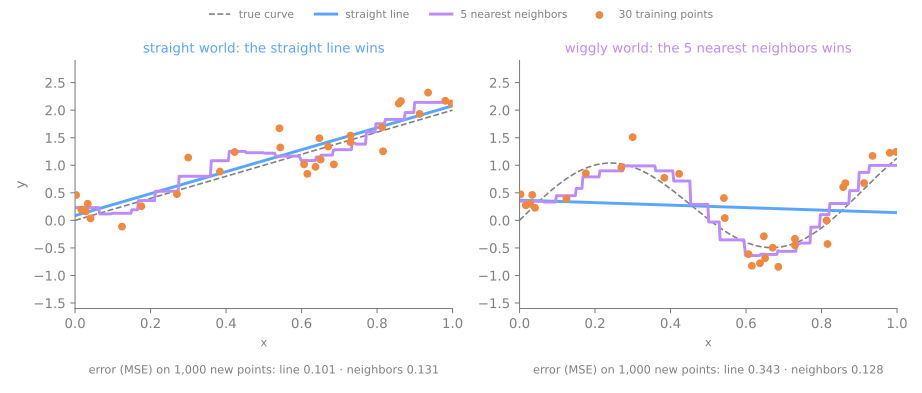
The line wins in the straight world (0.101 against 0.131) and loses badly in the wiggly one (0.343 against 0.128). Neither model is better; each one is better at something. The line assumes the answer changes at a constant rate, and it wins exactly where that assumption is true; the neighbors assume only that close inputs have close answers, which is true more often but costs them precision where the stronger assumption holds. Every model carries assumptions like these, its inductive bias, and the theorem says that no set of assumptions wins on every problem.
Two misreadings to avoid. The theorem does not say that all models are equal on your problem: on a given dataset some are much better, and finding which is the job of validation and model selection. And it does not say that experience is useless: real problems are not drawn at random from "all possible problems", which is why some families, like boosted trees on tables, win so often in practice. It says that the reason they win is a match between their assumptions and the data, and that the match has to be checked every time.
8. Ethics and responsibility
Stage 3. Models trained on historical data inherit historical bias. Before shipping a model, ask:
- Fairness — does the model perform equally across demographic groups? A credit model trained on biased decisions reproduces them at scale.
- Privacy — was the data collected with consent? Can individuals be re-identified?
- Transparency — can decisions be explained to those affected? (The explainability lesson covers it.)
- Feedback loops — does deploying the model change the data it will be retrained on? (Predictive policing is the canonical cautionary tale, and the next section works it out by hand.)
A model learns the past
A supervised model learns to reproduce its labels, and when the labels are past human decisions, it learns the decisions, not the truth they were meant to capture. Step 6 of the lab builds the smallest possible case: 4,000 past loan applicants from two groups, A and B, with the same distribution of repayment scores, judged by officers who approved A from a score of 50 up and B only from 65 up. A small tree is trained to imitate those decisions and then scores 2,000 new applicants (figure script):
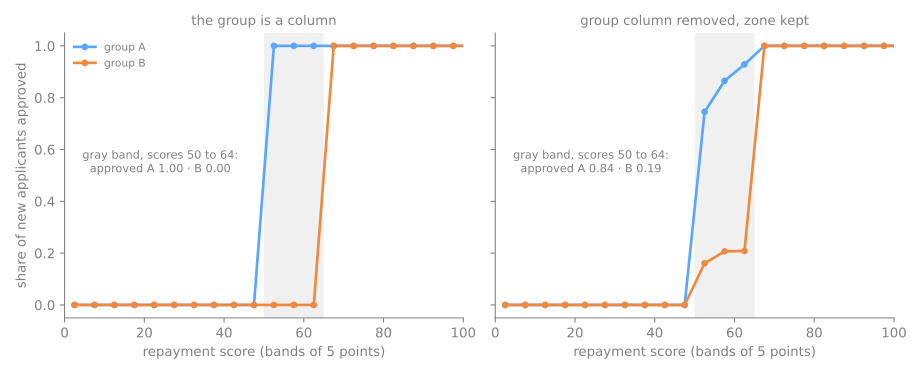
On the left the model has learned the double standard exactly: between 50 and 64, every applicant of group A is approved and none of group B, although the two groups repay alike. Nobody programmed that rule; it was in the labels. On the right the group column has been deleted — the usual first instinct — but the zone where people live has been kept, and 80% of group B live in one zone. The model uses the zone instead: 0.84 against 0.19 in the same band. A feature that stands in for a removed one is a proxy, and removing a sensitive column does not remove the bias as long as a proxy remains. What does help is to measure: compare the model's errors and decisions across groups, at equal scores, before and after deployment.
Warning
"The model said so" is never an acceptable justification for a decision that affects people. You — the practitioner — own the consequences.
9. Feedback loops: a model that writes its own data
Stage 4. The last question of the checklist is the least intuitive, because the data look perfectly honest. A city has two neighborhoods and one patrol car. Every day, a model sends the car where more crime has been recorded; the car records every incident it sees there, and in the other neighborhood only residents' calls reach the records, 2 a day. Neighborhood A has 10 incidents a day; B has 12. The history starts with 55 records in A and 45 in B. Day by day:
| day | the model predicts (A vs B records) | patrol | records after the day |
|---|---|---|---|
| 1 | 55 ≥ 45 | A | A 55 + 10 = 65 · B 45 + 2 = 47 |
| 2 | 65 ≥ 47 | A | A 75 · B 49 |
| 3 | 75 ≥ 49 | A | A 85 · B 51 |
| 10 | 145 ≥ 63 | A | A 155 · B 65 |
Every day the gap grows by 8 (10 recorded in A, 2 in B), so B can never catch up. After ten days the records say A has 2.4 times the crime of B (155 against 65), while B had more incidents every single day: had every incident been recorded, the two would tie on day 5 (105 each) and B would lead from day 6 on. Each record is a real incident; the records are wrong about where crime is because the model decides where to look. The simulator steps through the ten days and then reveals what really happened:
Retraining does not fix this, because each new model is trained on records the previous one shaped. The ways out change what is measured: send the patrol, some of the time, where the model does not expect crime (exploration), and compare incidents per patrolled day instead of raw totals. Step 7 of the lab runs both: with one day in five spent exploring, the estimates come out as 10 and 12 a day, the truth. Real predictive-policing systems show the same runaway on real records (Lum and Isaac, 2016; Ensign et al., 2018), and so do recommender systems that only learn from the items they chose to show.
10. Summary: five questions to take to every project
- Is the problem framed? Target, moment, metric and baseline, written down before the data are touched.
- What will the model meet? The goal is the expected loss on new data; a test set estimates it only if it stayed untouched and the world does not drift.
- Why this model? No free lunch: each family wins where its assumptions match the data, so compare several and validate.
- What did the labels teach it? A model learns the past, biases included; removing a column does not remove its proxies, so measure decisions across groups.
- Does the model choose its own data? If its decisions decide what gets recorded, retraining amplifies the error; explore and measure per unit of effort.
Advanced lab — no free lunch, a biased past and a loop that feeds itself
The fundamental lab measured generalization in a world you controlled. This part uses three more small worlds, each built to make one idea of the advanced approach visible: two problems with opposite winners, a past full of biased decisions, and a patrol that decides its own data. Continue in the same notebook, in the same session: step 5 uses np and true_curve from step 1.
How to do this lab in class (about 30 min, in pairs)
- Continue in the same Colab notebook, from step 5. If the session dropped, first run the cell of step 1 again (Runtime → Run before).
- As in the fundamental lab: Predict before running, compare with this page, and try the Simulations before opening the solution.
- Suggested pace: step 5 in 8 min; step 6 and the first simulation in 12 min; step 7 and the second simulation in 10 min.
Step 5 — no free lunch, measured
Predict. Two worlds, a straight one and the wiggly curve of step 1, and three models: the training mean (the baseline), a straight line, and 5 nearest neighbors. Which model wins in each world? Will any model win in both?
from sklearn.dummy import DummyRegressor
from sklearn.linear_model import LinearRegression
from sklearn.neighbors import KNeighborsRegressor

worlds = {'straight': lambda x: 2 * x, 'wiggly': true_curve}

def draw_world(world, n, seed):
    rng = np.random.default_rng(seed)
    x = rng.uniform(0, 1, n)
    return x.reshape(-1, 1), worlds[world](x) + rng.normal(0, 0.3, n)

models = {
    'mean (baseline)': DummyRegressor(),                    # always answers the training mean
    'straight line': LinearRegression(),
    '5 nearest neighbors': KNeighborsRegressor(n_neighbors=5),   # averages the 5 closest training points
}
print(f"{'error on new points':22s}{'straight':>10s}{'wiggly':>10s}")
for name, model in models.items():
    errors = []
    for world in worlds:
        X, y = draw_world(world, 30, seed=0)
        X_future, y_future = draw_world(world, 1000, seed=1)
        model.fit(X, y)
        errors.append(np.mean((y_future - model.predict(X_future)) ** 2))
    print(f"{name:22s}{errors[0]:10.3f}{errors[1]:10.3f}")
error on new points     straight    wiggly
mean (baseline)            0.464     0.364
straight line              0.101     0.343
5 nearest neighbors        0.131     0.128
These are the two panels of the figure in section 7. The straight line wins in the straight world and barely beats the baseline in the wiggly one (0.343 against 0.364); the neighbors win in the wiggly world and lose in the straight one. No row is best in both columns. The baseline row is the reference of section 5: a model that does not clearly beat it has learned nothing useful.
Step 6 — a model learns the past
Predict. 4,000 past loan decisions: scores from 0 to 100, distributed alike in groups A and B, but the officers approved A from 50 up and B only from 65 up. A small tree is trained to imitate them. Among new applicants with scores from 50 to 64, what share of each group will the model approve?
import pandas as pd
from sklearn.tree import DecisionTreeClassifier

rng = np.random.default_rng(0)
def applicants(n):
    group_B = rng.integers(0, 2, n)                               # 1 = group B, 0 = group A
    return pd.DataFrame({
        'score': rng.integers(0, 101, n),                         # ability to repay, 0 to 100: same in both groups
        'group_B': group_B,
        'zone': (rng.random(n) < np.where(group_B == 1, 0.8, 0.2)).astype(int),  # where they live (simulation)
    })

past = applicants(4000)
# the officers approved group A from a score of 50 up, but group B only from 65 up
past['approved'] = (past['score'] >= np.where(past['group_B'] == 1, 65, 50)).astype(int)

model = DecisionTreeClassifier(max_depth=3, random_state=0)      # a black box for now
model.fit(past[['score', 'group_B']], past['approved'])

new = applicants(2000)
new['approved'] = model.predict(new[['score', 'group_B']])

def approval(df):
    rate = df.groupby('group_B')['approved'].mean()
    return f"group A {rate[0]:.2f} · group B {rate[1]:.2f}"

print('approved, all new applicants: ', approval(new))
print('approved, scores 50 to 64:    ', approval(new[new['score'].between(50, 64)]))
approved, all new applicants:  group A 0.50 · group B 0.34
approved, scores 50 to 64:     group A 1.00 · group B 0.00
Across all applicants the gap looks moderate (0.50 against 0.34), because most scores fall where both rules agree. Between 50 and 64 it is total: 1.00 against 0.00. The model is an excellent student, it reproduces its labels without error, and that is exactly the problem: the labels were biased decisions. Nothing in the code mentions discrimination; the tree (the decision trees lesson opens it) found the split on group_B because it was the best way to imitate the officers.
Simulation: delete the column. The usual first fix is to drop group_B. Train the same tree on score and zone only (the zone column is already in the data: 80% of group B live in zone 1, 20% of group A do), predict the new applicants again and print the same two lines. Is the bias gone?
Solution
blind = DecisionTreeClassifier(max_depth=3, random_state=0)
blind.fit(past[['score', 'zone']], past['approved'])             # no group column
new['approved'] = blind.predict(new[['score', 'zone']])
print('share of group B in zone 1:', round(new.loc[new['zone'] == 1, 'group_B'].mean(), 2))
print('approved, all new applicants: ', approval(new))
print('approved, scores 50 to 64:    ', approval(new[new['score'].between(50, 64)]))
share of group B in zone 1: 0.82
approved, all new applicants:  group A 0.48 · group B 0.37
approved, scores 50 to 64:     group A 0.84 · group B 0.19
The model never sees the group, and still approves 0.84 of group A and 0.19 of group B with the same scores. It learned the rule through the zone: 82% of zone 1 is group B, so "zone 1" is almost "group B". The zone is a proxy. Deleting the sensitive column only made the bias harder to see; measuring the decisions by group, as these two lines do, is what reveals it.
Step 7 — a loop that feeds itself
Predict. The patrol of section 9, run for 30 days instead of 10. After a month, which neighborhood do the records say is more dangerous, and by how much?
true_per_day = {'A': 10, 'B': 12}          # incidents a day: B actually has more
records = {'A': 55, 'B': 45}               # the history the model starts from
for day in range(1, 31):
    hotspot = max(records, key=records.get)          # the "model": where more crime was recorded
    for hood in records:
        if hood == hotspot:
            records[hood] += true_per_day[hood]      # the patrol records every incident it sees
        else:
            records[hood] += 2                       # elsewhere only residents' calls: 2 a day
    if day in (1, 2, 3, 10, 30):
        print(f"day {day:2d}: patrol in {hotspot} · records A {records['A']:3d} · B {records['B']:3d}")
day  1: patrol in A · records A  65 · B  47
day  2: patrol in A · records A  75 · B  49
day  3: patrol in A · records A  85 · B  51
day 10: patrol in A · records A 155 · B  65
day 30: patrol in A · records A 355 · B 105
Days 1 to 10 are the table of section 9. After 30 days the records say A has 3.4 times the crime of B (355 against 105), and the ratio keeps growing: the longer the loop runs, the more certain the model becomes of something false. Every retraining on these records would confirm it.
Simulation: look where you do not look. Change the rule in two ways: on days 1, 6, 11, … (every fifth day, day % 5 == 1) send the patrol to the neighborhood it has patrolled less; on the other days, send it where it saw the most incidents per patrolled day. Count only what the patrol itself records. After 30 days, how many days did each neighborhood get, and what are the two estimates per day?
Solution
seen = {'A': 0, 'B': 0}                    # incidents the patrol itself recorded
days = {'A': 0, 'B': 0}                    # days the patrol spent there
for day in range(1, 31):
    if day % 5 == 1:                       # every fifth day, look where you did not look
        hotspot = min(days, key=days.get)
    else:                                  # otherwise go where the patrol saw the most per day
        hotspot = max(days, key=lambda h: seen[h] / days[h] if days[h] else 0)
    seen[hotspot] += true_per_day[hotspot]
    days[hotspot] += 1
print('days patrolled:', days)
print('incidents per patrolled day:', {h: seen[h] / days[h] for h in days})
The first exploration day (day 1) goes to A; the second (day 6) is the first visit to B, which shows 12 incidents against A's 10 per day, and from day 7 on the patrol goes mostly to B: 21 days against 9. Both changes were needed. Exploring alone would still compare raw totals, which A keeps winning; dividing by the days patrolled alone would never visit B to find out. Together they measure the same thing in both places, and the estimates match the truth, 10 and 12.
To close the lesson. In one sentence each: (1) why does neither the line nor the neighbors win in both worlds of step 5? (2) Why did deleting group_B not remove the bias? (3) What did the patrol model of step 7 get wrong, if every record was a real incident?
Your turn (advanced)
At home, with more time:
- The future outside the past. In step 5, draw the new points of the straight world from \(x\) between 1 and 1.5 instead of 0 and 1 (outside the training range). Which model wins now, and why can the neighbors not follow the line there?
- Two kinds of fairness. In step 6, compute the approval rate by group for all applicants and for each band of 10 points of score. Can a model have equal approval rates for both groups overall and still treat equal scores differently? Build one by changing the officers' rule.
- Proportional patrols. In step 7, instead of sending the patrol to the hotspot, split each day's patrol time in proportion to the records (A gets \(55/100\) of the first day, and its records grow by \(10 \times 0.55\)). Does the share of A in the records still grow, stay where it started or move toward the truth?
References
- Wolpert, D. H. "The Lack of A Priori Distinctions Between Learning Algorithms." Neural Computation 8 (1996). DOI
- Lum, K.; Isaac, W. "To Predict and Serve?" Significance 13, no. 5 (2016): 14–19 — a predictive-policing model trained on drug arrests sends police where police already were. DOI
- Ensign, D.; Friedler, S. A.; Neville, S.; Scheidegger, C.; Venkatasubramanian, S. "Runaway Feedback Loops in Predictive Policing." Proceedings of the Conference on Fairness, Accountability and Transparency, PMLR 81 (2018): 160–171 — the loop of section 9, as a mathematical model. Paper
- Barocas, S.; Hardt, M.; Narayanan, A. Fairness and Machine Learning: Limitations and Opportunities. MIT Press (2023) — biased labels, proxies and why removing a sensitive column is not enough. Free online