The path of this part
- One neuronlogistic regression as a neuron; the perceptron
- Hidden layersXOR, a hidden layer, nonlinear activations
- Forward passone matrix product per layer; counting parameters
- Backpropagationchain rule, six steps, a simulator
- In practicescaling, width, weight decay
A neuron is a logistic regression
\[ z = w^\top x + b, \qquad a = \varphi(z) \]Inputs \(x\), weights \(w\), bias \(b\), pre-activation \(z\), activation function \(\varphi\). With \(\varphi = \sigma\), the sigmoid \(\sigma(z) = 1/(1 + e^{-z})\), this is logistic regression: \(a\) is the probability of the positive class.
by hand
\(w = (2, -1)\), \(b = 0.5\), \(x = (1, 2)\): \(z = 2 \cdot 1 - 1 \cdot 2 + 0.5 = 0.5\) and \(a = \sigma(0.5) = 0.622\).
The perceptron (Rosenblatt, 1958)
Activation: a step, \(\hat y = +1\) if \(z > 0\), \(-1\) otherwise. Labels \(y \in \{-1, +1\}\).
Visit the points one at a time. If point \(i\) is wrong or on the line (\(y_i z_i \le 0\)), with step size \(\eta\):
\[ w \leftarrow w + \eta \, y_i \, x_i, \qquad b \leftarrow b + \eta \, y_i \]After the update the point's signed score \(y_i z_i\) grows by \(\eta(\lVert x_i \rVert^2 + 1) > 0\): the line tilts toward classifying it.
Three updates by hand, step by step
Six points: A, E, F are \(+1\); B, C, D are \(-1\). Start \(w = (0, 0)\), \(b = 0\), \(\eta = 1\). Predict. Which points will cause an update, and how many epochs until one passes without a mistake?
XOR: why one line is not enough
\((0, 1)\) and \((1, 0)\) are \(+1\); \((0, 0)\) and \((1, 1)\) are \(-1\). A separating line \(w_1 x_1 + w_2 x_2 + b = 0\) would need:
- \((0,0)\) negative: \(b < 0\)
- \((0,1)\), \((1,0)\) positive: \(w_2 + b > 0\), \(w_1 + b > 0\)
- \((1,1)\) negative: \(w_1 + w_2 + b < 0\)
Add the middle two: \(w_1 + w_2 + 2b > 0\), so \(w_1 + w_2 + b > -b > 0\). Contradiction.
Simulator: the perceptron on XOR
Choose the XOR preset and press Whole epoch a few times. Predict. Will the mistakes per epoch ever reach zero? Where do the weights go?
The same wall stops logistic regression
A noisy XOR: 400 points around the four corners (205 and 195 per class), 5-fold cross-validation.
logistic regression
its probabilities
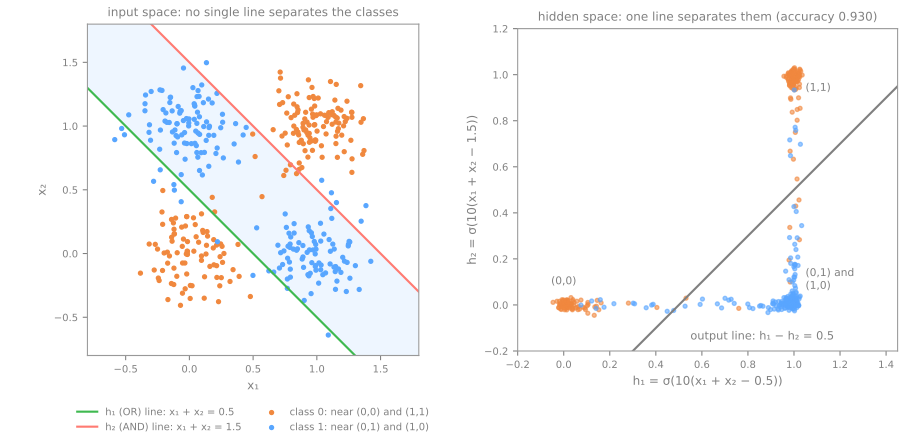
A hidden layer solves XOR
- \(h_1\): \(x_1 + x_2 - 0.5 > 0\), OR
- \(h_2\): \(x_1 + x_2 - 1.5 > 0\), AND
- output: \(h_1 - h_2 - 0.5 > 0\), XOR
| \(x_1\) | \(x_2\) | \(h_1\) | \(h_2\) | \(z_{\text{out}}\) | out |
|---|---|---|---|---|---|
| 0 | 0 | 0 | 0 | −0.5 | 0 |
| 0 | 1 | 1 | 0 | 0.5 | 1 |
| 1 | 0 | 1 | 0 | 0.5 | 1 |
| 1 | 1 | 1 | 1 | −0.5 | 0 |
Row \((1, 1)\): \(z_1 = 1.5 \Rightarrow h_1 = 1\); \(z_2 = 0.5 \Rightarrow h_2 = 1\); \(z_{\text{out}} = 1 - 1 - 0.5 = -0.5 \Rightarrow 0\). Every weight chosen by hand.
The hidden layer builds new features
From step to sigmoid: something to differentiate
The step has derivative 0 everywhere: the gradient says nothing. Replace it by a sigmoid and multiply every weight by 10:
| \(x_1\) | \(x_2\) | \(h_1\) | \(h_2\) | P(XOR = 1) |
|---|---|---|---|---|
| 0 | 0 | 0.007 | 0.000 | 0.007 |
| 0 | 1 | 0.993 | 0.007 | 0.992 |
| 1 | 0 | 0.993 | 0.007 | 0.992 |
| 1 | 1 | 1.000 | 0.993 | 0.007 |
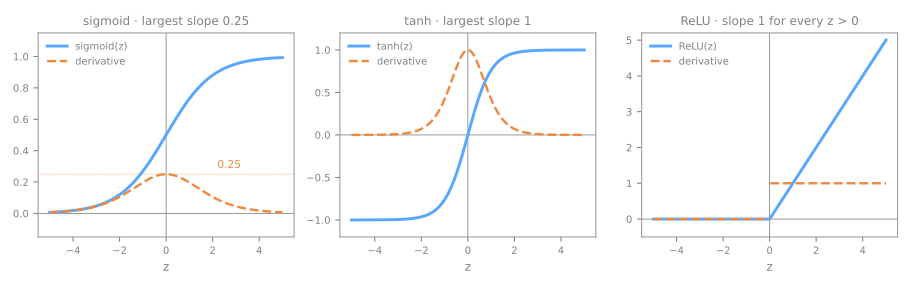
Activation functions
| largest derivative | |
|---|---|
| sigmoid | 0.25, at \(z = 0\) |
| tanh | 1, at \(z = 0\) |
| ReLU | 1, for every \(z > 0\) |
Without a nonlinearity, layers collapse
\(W_2 (W_1 x + b_1) + b_2\) is one layer with weights \(W_2 W_1\) and bias \(W_2 b_1 + b_2\): a linear function of a linear function is linear.
two linear layers
one merged layer
ReLU between
On the noisy XOR, 8 hidden units:
| activation | CV accuracy |
|---|---|
identity | 0.510 |
relu | 0.983 |
The forward pass: one matrix product per layer
\[ z = W x + b^{h}, \quad h = \sigma(z), \quad u = v^\top h + b^{y}, \quad \hat{y} = \sigma(u) \]\(W\): one row of weights per hidden unit; \(b^h\), \(b^y\): biases; \(v\): the output weights; \(u\): the output pre-activation. For a batch of rows \(X\): \(H = \sigma(X W^\top + b^h)\), which is why networks run so well on GPUs (graphics processing units), machines for multiplying matrices.
a 2-2-1 network, one example \(x = (0.5, 0.8)\), target \(y = 0\)
\(W = \begin{pmatrix} 0.2 & 0.4 \\ 0.6 & 0.8 \end{pmatrix}\), \(b^h = (0.1, 0.2)\), \(v = (0.3, 0.5)\), \(b^y = 0.4\)
Counting parameters
A layer with \(n_\text{in}\) inputs and \(n_\text{out}\) units: \(n_\text{in} \cdot n_\text{out}\) weights and \(n_\text{out}\) biases, \((n_\text{in} + 1) \cdot n_\text{out}\) parameters. Predict. One hidden layer of 256 units, or two of 64: which has more?
| architecture | parameters |
|---|---|
| 2 → 2 → 1 | 9 |
| 64 → 10 | 650 |
| 64 → 32 → 10 | 2,410 |
| 64 → 256 → 10 | 19,210 |
| 64 → 64 → 64 → 10 | 8,970 |
Backpropagation: the chain rule, organized
A first-layer weight reaches the loss \(L = (\hat y - y)^2\) only through everything after it:
\[ w_{11} \;\to\; z_1 \;\to\; h_1 \;\to\; u \;\to\; \hat y \;\to\; L \]- loss gradient: \(\partial L / \partial \hat y = 2(\hat y - y)\)
- output delta: \(\delta_y = \partial L / \partial u = 2(\hat y - y) \cdot \hat y (1 - \hat y)\), since \(\sigma'(u) = \hat y(1 - \hat y)\)
- output weights: \(\partial L / \partial v_{1j} = \delta_y \, h_j\)
- hidden deltas: \(\delta_{h_j} = \delta_y \, v_{1j} \cdot h_j (1 - h_j)\)
- hidden weights: \(\partial L / \partial w_{jk} = \delta_{h_j} \, x_k\)
- update, with step \(\eta\): \(p \leftarrow p - \eta \, \partial L / \partial p\) for every parameter \(p\)
Backpropagation, step by step
The 2-2-1 network of stage 3. Step 1 is the forward pass; steps 2 to 6 send the gradient back; step 7 updates with \(\eta = 0.5\). Predict. Which of the 9 gradients will be the smallest? (Click the simulator to use the arrow keys inside it.)
In practice: scale the inputs
Spambase: 4,601 e-mails, 57 features, standard deviations from 0.076 to 606.
| MLP (multi-layer perceptron) | CV accuracy |
|---|---|
| raw inputs | 0.927 |
StandardScaler first | 0.948 |
Width and weight decay, on noisy moons
alpha, the L2 penalty on the weights (weight decay), do to the 100 units?| hidden units | train | CV |
|---|---|---|
| logistic regression | 0.830 | |
| 1 | 0.842 | 0.843 |
| 3 | 0.897 | 0.873 |
| 10 | 0.938 | 0.893 |
| 100 | 0.997 | 0.857 |
100 units, alpha | train | CV |
|---|---|---|
| 0.0001 | 0.997 | 0.857 |
| 0.01 | 0.993 | 0.880 |
| 0.1 | 0.939 | 0.903 |
| 1 | 0.914 | 0.917 |
| 10 | 0.837 | 0.830 |
The boundaries
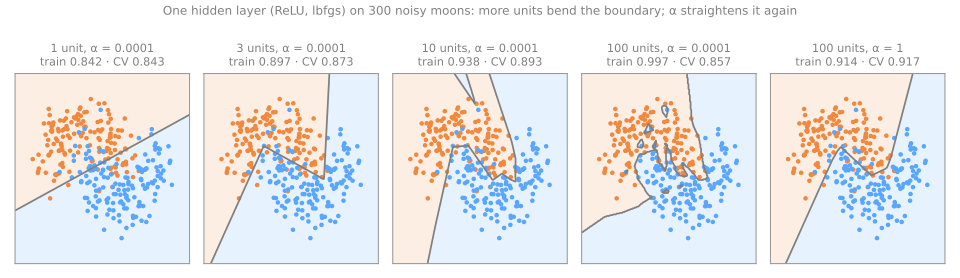
alpha (and the width) with cross-validation.Summary
- A neuron = weighted sum + activation; with a sigmoid, logistic regression; with a step, the perceptron.
- One neuron draws one line: XOR needs a hidden layer, which computes new features.
- The activation must be nonlinear, or the layers collapse; ReLU keeps the gradient from vanishing.
- Forward pass: one matrix product per layer. Backpropagation: deltas sent back, one exact gradient per weight.
- In practice: scale, then tune width and
alphaby cross-validation.
| symptom | what to do |
|---|---|
| training near 1, CV well below | raise alpha, or fewer units |
| training and CV at the logistic-regression level | more units, less alpha, a nonlinear activation |
A neural network on handwritten digits, steps 1 to 5
- 1,797 digits of 8 × 8 pixels: name the digit. Lock the test set away, set a baseline, compare three models on the same folds, tune the width and
alpha. - Download the lab notebook and open it in Jupyter or Colab; it runs in about a minute.
- At every step, answer the Predict before running.
- Simulations: a network without activation (step 4) and how narrow can the network be? (step 5).
Pace: steps 1 to 3 in 6 min; step 4 and the first simulation in 10 min; step 5 and the second in 14 min.