The rule from the preprocessing lesson
- Every step that learns from the data: the median of an imputer, the mean and standard deviation of a scaler, the categories of an encoder.
- It is fit on the training rows only.
- Then it is replayed, unchanged, on every other row: the test set, a validation split, next month's data in production.
fit and transform calls that must stay in the right order, on the right data, forever.The path of this part
- The manual workflowseven calls, three bugs, measured
- One Pipelinefit and predict, step by step
- Real columnsColumnTransformer: a branch per group of columns
- An honest scorethe leak it prevents, measured
The data and the model
California housing
- 20,640 districts
- 8 numeric columns (
total_bedroomshas holes) - 1 text column,
ocean_proximity - target: the median house value
a black box: k-NN (k-nearest neighbors)
Predicts a district as the average of the 10 most similar training districts.
Two properties matter here: it depends on the scale of the columns, and it is fast.
Preprocessing: fill the holes with the median, then standardize. The k-NN lesson studies the model itself.
The careful manual workflow
imputer = SimpleImputer(strategy='median')
scaler = StandardScaler()
model = KNeighborsRegressor(n_neighbors=10)

A_train = scaler.fit_transform(imputer.fit_transform(X_train[num]))   # learn on train
model.fit(A_train, y_train)
A_test = scaler.transform(imputer.transform(X_test[num]))             # replay on test
pred = model.predict(A_test)
careful workflow
always the training mean
Seven calls, and the order matters
fit_transformon train,transformon test.- Imputer before scaler.
- The same eight columns, in the same order.
Each bug below changes one thing in the prediction code. The trained model is the same every time.
Bug 1, step by step: fit on which rows?
Training 200, NaN, 400, 600, 800; new NaN, 900 (NaN, not a number: missing). Predict. Re-fit on the 2 new rows, or on all 7: what does 900 become?
Bug 1 on the real data: it depends on how the rows arrive
| the scaler is re-fit on… | MAE |
|---|---|
| the whole test set at once | $42,814 |
| each region's batch | $65,754 |
| one district at a time | $116,049 |
- Invisible on the whole test set: 4,128 random districts have almost the training statistics; the MAE even comes out $209 lower, by chance.
- Regional batches are re-centered on themselves: the neighbors found are no longer the right ones.
- One row has zero spread: every district becomes the same point, one distinct prediction for 4,128 districts.
Bug 2: a step forgotten at prediction time
imputer forgotten
the model refuses: Input X contains NaN.
the lucky case: an error
scaler forgotten
silent: raw numbers (a total_rooms of 2,000 where it learned values around 0), a confident prediction for every district
Bug 3: a different column order
The model receives numbers, not names: column 5 is "population" only because it was column 5 during training. Swap households and population:
sent as an array
a district has about three times more residents than households; the only hint is a UserWarning
sent as a DataFrame
scikit-learn compares the names with those of fit and refuses.
Six versions of the prediction code
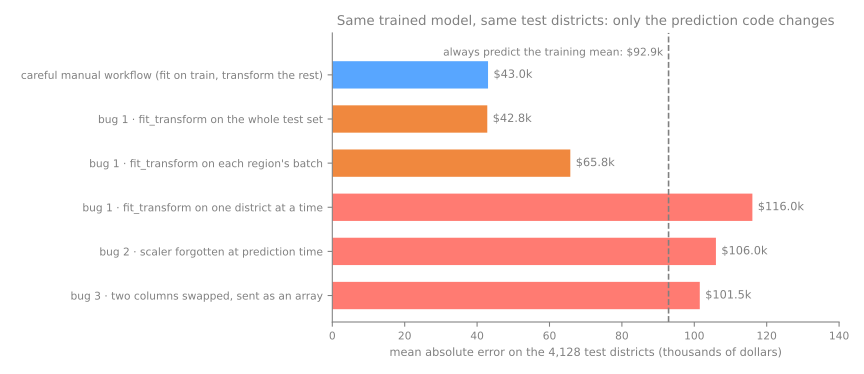
Three of the six bars are worse than ignoring the data. The most dangerous is the second one: the bug that looks correct.
Pipeline: one estimator, many steps
pipe = make_pipeline(SimpleImputer(strategy='median'), StandardScaler(),
                     KNeighborsRegressor(n_neighbors=10))
pipe.fit(X_train[num], y_train)            # every step learns from the training rows
pred_pipe = pipe.predict(X_test[num])      # every step replays what it learned
MAE
one at a time
4,128 predictions one by one = all at once
swapped columns
refused: the names must match those of fit
The three bugs, gone by construction
- Bug 1.
pipe.predictnever callsfiton a transformer: the batch size stops mattering. - Bug 2. There is no separate prediction code in which to forget a step: the steps travel inside the object.
- Bug 3. The pipeline hands the DataFrame to its first step, which checks the names.
fit + transform); the last can be anything with fit. The pipeline exposes the methods of its last step: predict, score, predict_proba.What fit and predict do, step by step
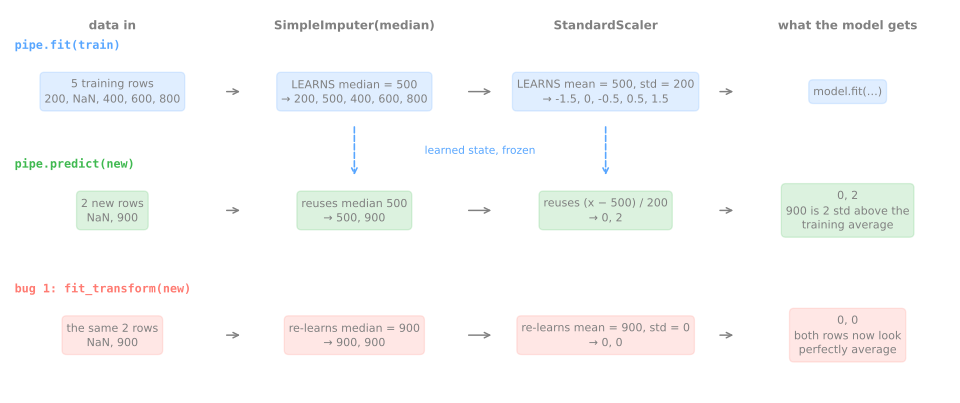
fit: each transformer is fit on what it receives and transforms it for the next one; the last step is only fit. predict: only transform, with the parameters frozen at fit time.
A spy between the steps
A do-nothing step that reports, for total_bedrooms, the missing values and the mean.
| call | rows | missing | mean |
|---|---|---|---|
| fit · raw | 16,512 | 163 | 538.92 |
| fit · imputed | 16,512 | 0 | 537.92 |
| predict · raw | 4,128 | 44 | 533.66 |
| predict · scaled | 4,128 | 0 | −0.01 |
No: the test rows are measured with the ruler of the training rows. A test mean of exactly 0.00 would be the symptom of bug 1.
During fit, only the 16,512 training rows exist. The 44 test holes get the training median.
Pipeline or make_pipeline
pipe_named = Pipeline([('impute', SimpleImputer(strategy='median')),
                       ('scale', StandardScaler()),
                       ('model', KNeighborsRegressor(n_neighbors=10))])
make_pipelinenames each step after its class:'simpleimputer','standardscaler','kneighborsregressor'.Pipelinetakes the names from you.
Same kind of object; names only matter when you refer to a step later. Short explicit names pay off in long pipelines.
Different columns, different treatments: ColumnTransformer
preprocess = ColumnTransformer([
    ('num', make_pipeline(SimpleImputer(strategy='median'), StandardScaler()), num),
    ('cat', OneHotEncoder(handle_unknown='ignore', sparse_output=False), ['ocean_proximity']),
])
full = make_pipeline(preprocess, KNeighborsRegressor(n_neighbors=10))
full.fit(X_train, y_train)                 # the raw 9-column table goes in
with ocean_proximity
each branch
a triple (name, transformer, columns); a branch can itself be a pipeline
Watch the columns travel
What actually comes out
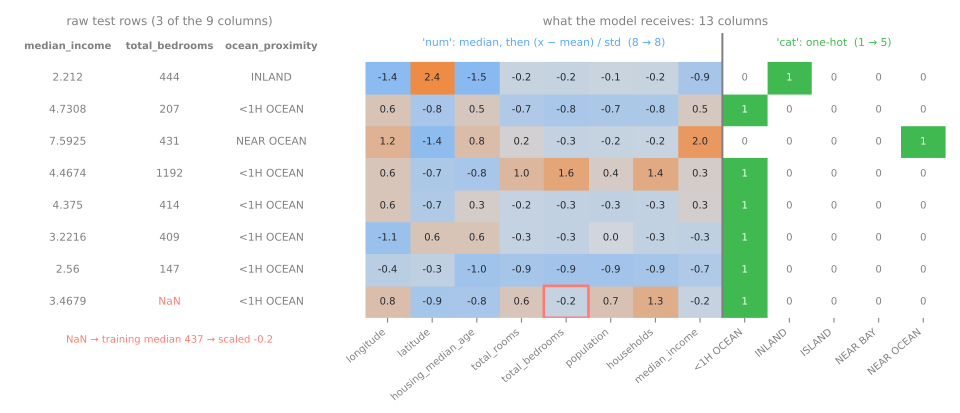
get_feature_names_out says what each of the 13 columns is: the prefix is the branch (num__, cat__), the one-hot columns carry the category. The missing total_bedrooms receives the training median, 437.
Which columns go where
remainder
Columns no branch mentions are dropped by default: 2 columns out.
'passthrough' appends them unchanged: 9 columns, but unscaled (and one is text).
selectors
make_column_selector(dtype_include='number') picks columns by type when fit.
They trust the types: a zip code stored as a number lands in the numeric branch.
'drop' is the safe default: a forgotten identifier never reaches the model silently. Explicit lists say exactly what happens.Robust to column order and to new categories
- The nine columns in reverse order: identical predictions. The
ColumnTransformerselects by name, so bug 3 disappears. - A district relabeled
'LAKE', a category never seen: zeros in the five one-hot columns and a prediction, $90,030, the same as with its real label.
handle_unknown='ignore' the same row raises Found unknown categories, and one new value in production takes the whole service down. ISLAND has only 5 districts in the whole table.The leak a pipeline prevents
Fit a step on all 20,640 districts before the split, or inside the pipeline. Two kinds of step:
a scaler
learns means and standard deviations; never looks at the price
a target encoder
replaces each zone by the average price of that zone (zones: coordinates rounded to ~1 km)
12,590 zones · 8,237 with a single district · 44% of test zones unseen in training
The size of a leak depends on what the step learns
| encoder fit on all rows | $14,567 |
| encoder inside the pipeline | $42,552 |
| no zone at all | $60,383 |
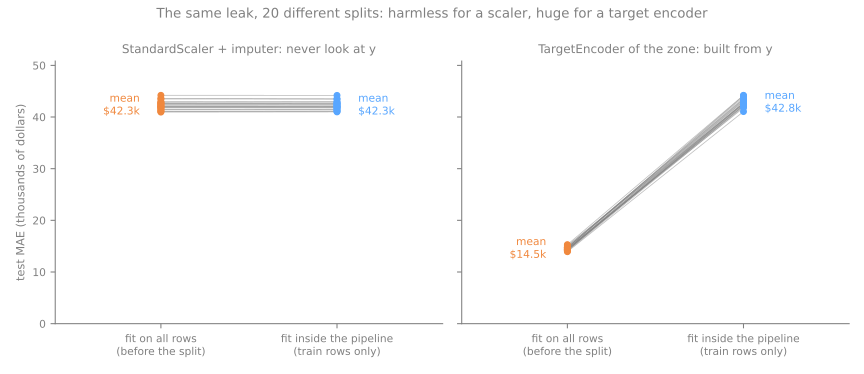
- A district alone in its zone: its "zone price" is its own price, and the model reads the answer off its input.
- Over 20 splits: the scaler leak moves the MAE by $4 on average; the encoder leak makes it look $28,300 smaller.
Simulator: fit on which rows?
Predict. Switch to test = later period, then to fit on all rows. Do the test rows look more or less shifted? Did the model get any better?
Summary
- Fitted steps: fit on train, replay unchanged. By hand, the rule breaks in three ways.
- The most dangerous bug is the one that looks correct on a notebook test set.
Pipeline:fitwalks the steps withfit_transform,predictonly withtransform. Same predictions, the three bugs gone.ColumnTransformer: a branch per group of columns, selected by name;remainder='drop';handle_unknown='ignore'.- The size of a leak depends on what the step learns: $4 for a scaler, $28,300 for a target encoder.
| symptom | what to do |
|---|---|
| fine in the notebook, bad in production | fit once, inside a pipeline |
| a score far better than expected | put every fitted step inside the pipeline |
From raw Titanic rows to an honest score, steps 1 to 5
- 891 raw passengers, text and holes included; a k-NN classifier as the black box.
- Download the lab notebook and open it in Jupyter or Colab (File → Upload notebook). Run the cells in order, in one session.
- Load, split once, build the preprocessing column by column, fit on train and score once on test, read what each step learned.
- At every step, answer the Predict before running.
- Simulations: the same recipe without the scalers (step 4) and the preprocessing fit on all 891 passengers (step 5).
Pace: steps 1 to 3 in 10 min; step 4 and the first simulation in 10 min; step 5 and the second in 10 min.