Most tasks are about texts, not words
support
find the FAQ (frequently asked questions) entry that answers a question
operations
group support tickets
search
retrieve the documents that match a query
The path of this part
- Average the wordsmean of GloVe vectors; order and negation vanish
- Words in contextTransformers: one word, several vectors
- One vector per sentenceSentence-BERT against TF-IDF (term frequency × inverse document frequency) and averaging; other languages
- Searchsemantic search is k-nearest neighbors
The obvious answer: average the word vectors
| "the movie was great" | first four of the 50 GloVe (global vectors) numbers |
|---|---|
| the | 0.418 · 0.25 · −0.412 · 0.122 … |
| movie | 0.308 · 0.172 · −0.233 · 0.023 … |
| was | 0.087 · −0.194 · −0.243 · −0.334 … |
| great | −0.027 · 1.336 · −1.028 · −0.373 … |
| mean | 0.197 · 0.391 · −0.479 · −0.141 … |
By hand: \((0.418 + 0.308 + 0.087 - 0.027)/4 = 0.1965\). Costs nothing, needs no training.
What averaging loses
| 1.00 | the dog bit the man / the man bit the dog |
| 0.99 | the movie was good / the movie was not good |
| 0.96 | the movie was great / the film was excellent |
| 0.66 | the stock market fell sharply today / my cat likes to sleep on the couch |
order is gone
same words, same mean: exactly 1.00
negation barely registers
"not" is one word in five
everything looks similar
unrelated sentences still score 0.66
Transformers, in one slide
- A Transformer (Vaswani et al., 2017) reads the whole sentence at once.
- It cuts the text into subword tokens (a vocabulary of about 30,000 pieces): no word is ever out of vocabulary.
- In each layer, every token's vector is recomputed as a weighted mix of all the tokens (attention).
- BERT (Bidirectional Encoder Representations from Transformers, Devlin et al., 2019): trained to fill in hidden words; one contextual vector per token.
Embeddings are unbelievably useful → em · ##bed · ##ding · ##s · are · un · ##bel · ##ie · ##va · ##bly · useful
One word, several vectors
| river 1 | river 2 | river 3 | money 4 | money 5 | money 6 | |
|---|---|---|---|---|---|---|
| river 1 | 1.00 | 0.83 | 0.86 | 0.76 | 0.76 | 0.76 |
| river 2 | 0.83 | 1.00 | 0.84 | 0.72 | 0.72 | 0.73 |
| money 4 | 0.76 | 0.72 | 0.72 | 1.00 | 0.88 | 0.86 |
| money 5 | 0.76 | 0.72 | 0.73 | 0.88 | 1.00 | 0.82 |
Sentence-BERT: trained to compare sentences
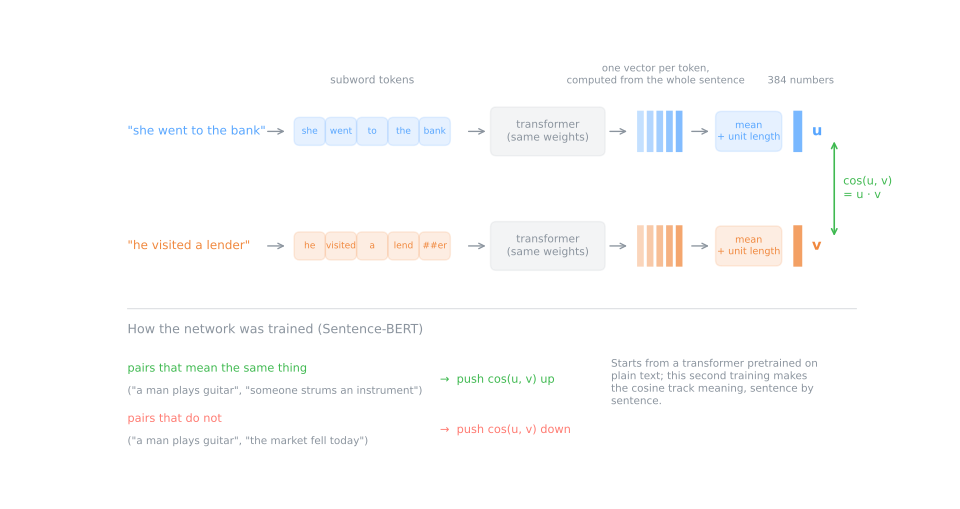
Mean pooling: average the token vectors, each already carrying its context.
Sentence-BERT (Reimers & Gurevych, 2019) adds training: cosine up for pairs that mean the same, down for pairs that do not.
Using sentence-transformers
E = model.encode(["the movie was great", "the film was excellent",
                  "the stock market fell sharply today"], normalize_embeddings=True)
E @ E.T     # with unit rows, the dot product is the cosine
size
paraphrases
the model
Averaged GloVe gave 0.96 against 0.66: now the scale is used from bottom to top.
Three representations, the same pairs
TF-IDF, averaged GloVe vectors and Sentence-BERT (SBERT) on eight pairs, each probing one property:
| pair | TF-IDF | avg GloVe | SBERT |
|---|---|---|---|
| paraphrase | 0.28 | 0.96 | 0.88 |
| paraphrase, other words | 0.19 | 0.92 | 0.56 |
| same need, other words | 0.15 | 0.92 | 0.68 |
| negation | 0.82 | 0.99 | 0.82 |
| word order | 1.00 | 1.00 | 0.98 |
| bank: river vs money | 0.29 | 0.92 | 0.60 |
| apple: company vs fruit | 0.18 | 0.87 | 0.23 |
| unrelated | 0.04 | 0.66 | 0.02 |
Before reading the next slide: which column would you trust to separate related from unrelated?
Reading the table
TF-IDF
measures shared words: paraphrases without them score 0.15 to 0.28
avg GloVe
says "similar" to everything: 0.66 to 1.00, no threshold works
SBERT
uses the whole scale: 0.02 to 0.88; the two "apples" score 0.23
Other languages
| pair (Portuguese) | English-only | multilingual |
|---|---|---|
| o filme foi ótimo / o longa foi excelente | 0.65 | 0.66 |
| esqueci minha senha / não lembro a senha da conta | 0.40 | 0.81 |
| o filme foi ótimo / the movie was great | 0.08 | 0.98 |
| o filme foi ótimo / a bolsa de valores caiu hoje | 0.40 | −0.02 |
Semantic search is k-nearest neighbors
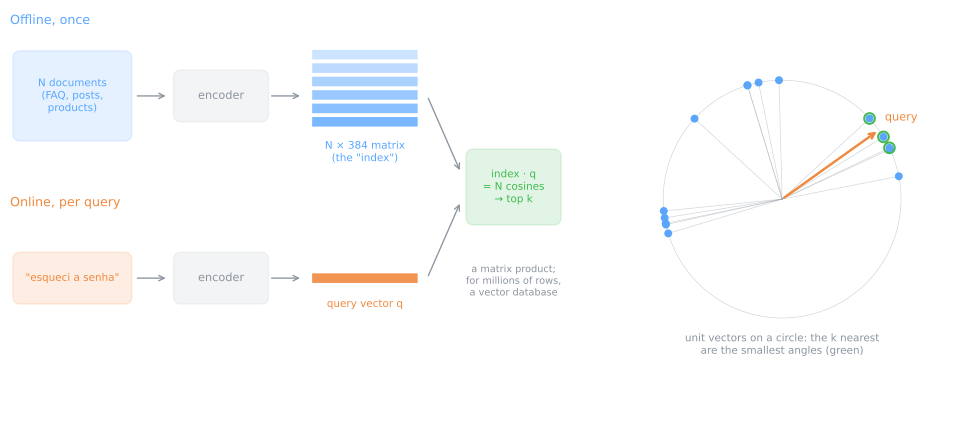
Encode the collection once; for each query, one matrix product gives every cosine. No labels, no prediction: only finding neighbors.
An FAQ in Portuguese, eight entries
| query | 1st answer | cos |
|---|---|---|
| esqueci minha senha | Como faço para trocar a senha da minha conta? | 0.68 |
| onde está minha encomenda? | Como rastrear o meu pedido? | 0.60 |
| desisti da compra | Como cancelar uma compra que ainda não foi enviada? | 0.62 |
| o celular veio com defeito | Posso devolver um produto depois de usado? (warranty 2nd, 0.24) | 0.26 |
| I need a copy of my invoice | Como faço para trocar a senha… (miss) | 0.43 |
Simulator: embeddings vs TF-IDF
Predict. For the query "erro 402", which ranking wins, embeddings or TF-IDF? Then type your own query.
What the simulator shows
embeddings
TF-IDF
Summary
- Averaging word vectors: free, but blind to order and negation, and everything looks alike.
- A Transformer gives each token a contextual vector: two "banks", two vectors.
- Sentence-BERT: pooled and trained so that the cosine tracks meaning, over the whole scale.
- Choose a model trained on your language.
- Semantic search = nearest neighbors; check negation, low and close scores, and rare exact tokens.
Sentence similarity in Portuguese, steps 1 to 5
- ASSIN 2: 2,448 test pairs of Brazilian Portuguese sentences rated by people from 1 to 5.
- Score them with TF-IDF and two sentence-transformer models, measure how well each follows the human score (Spearman), read where they disagree, and search the 3,659 sentences.
- Download the lab notebook and open it in Colab or Jupyter; in Colab run
!pip install sentence-transformersfirst. - Simulations: TF-IDF on pieces of words (step 2) and how much comes from context? (step 3).
Pace: steps 1 and 2 and the first simulation in 12 min; step 3 and the second in 10 min; steps 4 and 5 in 13 min.