The path of this part
- Tell the storya topic per word slot, then a word from that topic
- The Dirichlet priorhow mixed is a typical document?
- Fit real posts2,155 posts, top words, ARI with the forums
LDA: a story of how the words got there
Latent Dirichlet allocation (Blei, Ng & Jordan, 2003):
- each topic \(k\) is a probability distribution \(\varphi_k\) over the vocabulary;
- each document \(d\) has its own mixture of topics \(\theta_d\), e.g. \((0.8, 0.2)\);
- for every word slot: draw a topic \(z\) from \(\theta_d\), then a word from \(\varphi_z\).
\(\theta_{d,k}\): share of topic \(k\) in document \(d\) · \(\varphi_{k,w}\): probability of word \(w\) in topic \(k\). Word order plays no part: bag-of-words counts are enough.
The story by hand
Predict. In a document that is 80% sports, which is more likely, team or rocket, and by how much?
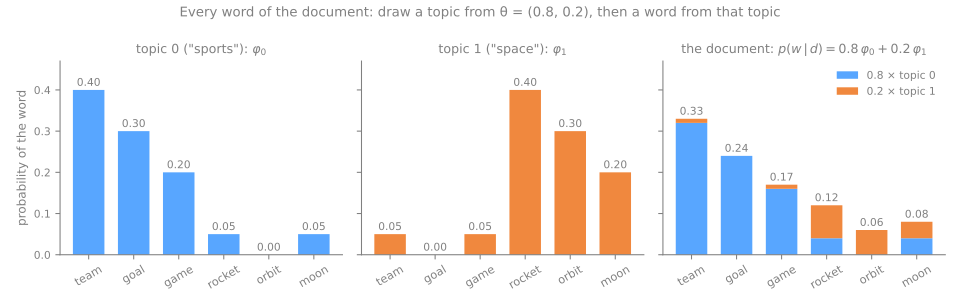
\(\theta = (0.8, 0.2)\): 80% sports, 20% space.
\(p(\textit{team}) = 0.8 \times 0.40 + 0.2 \times 0.05 = 0.33\)
\(p(\textit{rocket}) = 0.8 \times 0.05 + 0.2 \times 0.40 = 0.12\)
Following the story, 4 of 12 slots drew the space topic, and they are exactly where moon, orbit, rocket, orbit appear.
The Dirichlet prior: how mixed is a document?
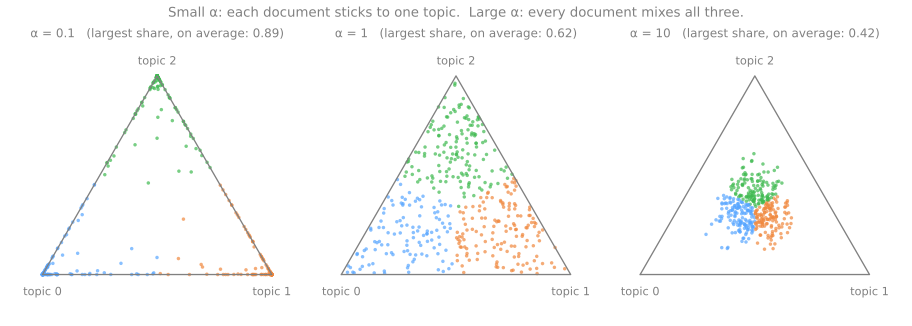
| \(\alpha\) | largest share |
|---|---|
| 0.1 | 0.89 |
| 1 | 0.62 |
| 10 | 0.42 |
\(\theta_d\) is drawn from a Dirichlet of parameter \(\alpha\). In scikit-learn, doc_topic_prior, \(1/k\) by default: documents that concentrate on few topics.
Simulator: write a document the LDA way
Predict. With \(\alpha = 0.1\), will the documents you draw come out in one color or in all three?
From the story to scikit-learn
lda = LatentDirichletAllocation(
        n_components=4, random_state=0).fit(X)
phi = lda.components_     # one row per topic
theta = lda.transform(X)  # one row per document
label = theta.argmax(axis=1)
X: bag-of-words counts, documents × words.- A row of
components_, divided by its sum, is an estimated \(\varphi_k\). - A row of
transformis the document's \(\theta_d\).
LDA on 2,155 real posts
Four forums of 20 Newsgroups (graphics, hockey, space, religion); 5,725 words of 3+ letters in at least 5 posts and at most half of them. Predict: which forum comes out cleanest?
| jpeg don pts like think play period gif |
| god space people think just jesus time like |
| team game hockey season games nhl play year |
| image edu data graphics space available software program |
Summary
- A topic is a distribution \(\varphi_k\) over words; a document, a mixture \(\theta_d\) of topics.
- \(p(w \mid d) = \sum_k \theta_{d,k}\, \varphi_{k,w}\): the topics' probabilities, mixed.
- \(\alpha\) small: one topic per document; \(\alpha\) large: everything mixed.
- Fitting runs the story backwards on counts:
components_holds the topics,transformthe mixtures.
To close the fundamental part
- Why does LDA need only word counts, and not word order?
- Which of the six words could never appear in a document that is 100% space?
- What would the documents of a corpus look like with \(\alpha = 10\)?
In the lab: step 2 fits LDA on five other forums (overview page). Next: the fundamental slides of E3.2 NMF.