The path of this part
- X ≈ WHtopics in H, mixtures in W, all ≥ 0
- Why non-negativewhole themes, not contrasts
- NMF on the postsfour forums, four topics
NMF: \(X \approx WH\), with nothing negative
\[ X_{\,n \times V} \;\approx\; W_{\,n \times k}\; H_{\,k \times V}, \qquad W \ge 0,\; H \ge 0 \]\(n\) documents, \(V\) words, \(k\) topics. \(X\): the TF-IDF matrix (term frequency × inverse document frequency).
rows of \(H\)
the topics: a weight for every word
rows of \(W\)
how much of each topic a document contains
Non-negative matrix factorization (Lee & Seung, 1999): the shape of PCA (principal component analysis), plus the constraint that every entry is \(\ge 0\). It minimizes \(\lVert X - WH \rVert^2\).
NMF on the 11 sentences
Predict. LDA failed on these sentences in 19 seeds out of 20. Will NMF find the three themes?
Topics: launch rocket satellite orbit · bread oven bake fresh · team game goal won
Clean split: every single-theme sentence in its theme.
init='nndsvda' starts from an SVD (singular value decomposition), not a random point: one reason the result is stable.
| sentence | space | cooking | sports |
|---|---|---|---|
| 0 (sports) | 0.00 | 0.00 | 0.71 |
| 3 (space) | 0.62 | 0.00 | 0.00 |
| 9 team watched the rocket launch… | 0.29 | 0.00 | 0.45 |
| 10 astronauts ate fresh bread… | 0.10 | 0.41 | 0.00 |
Why non-negative? A comparison with SVD
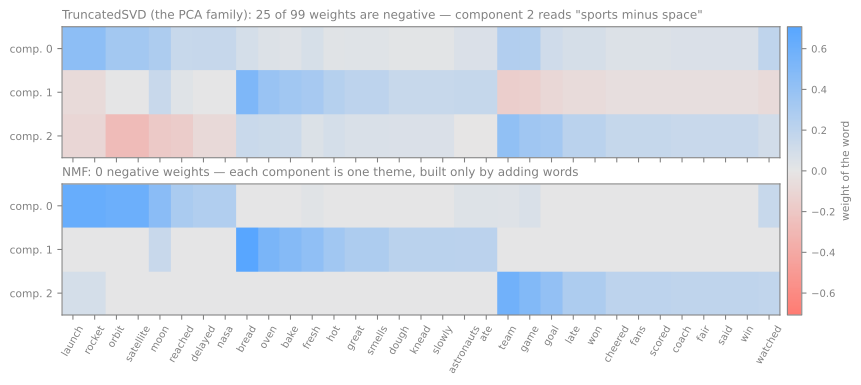
Simulator: NMF parts versus SVD directions
Predict. From random weights, press step: will the NMF rows end up as whole themes or as contrasts like the SVD's? Will its error reach the SVD's?
NMF on the posts
Predict. Same 2,155 posts and vocabulary as LDA, now as TF-IDF, four topics. Will NMF blur the forums as LDA did?
| graphics thanks files image program file know windows |
| god jesus people believe christ faith bible christians |
| game team hockey players play games season nhl |
| space nasa launch shuttle moon orbit lunar earth |
LDA
NMF
Summary
- \(X \approx WH\) with \(W, H \ge 0\): rows of \(H\) are topics, rows of \(W\) the amount of each topic in a document.
- Nothing negative means parts that add up: whole themes, not "sports minus space".
- The weights are amounts, not probabilities: read them directly.
- Here NMF beat LDA (0.767 against 0.456); in the lab the order is reversed. No model wins everywhere.
To close the fundamental part
- What is in a row of \(H\), and what is in a row of \(W\)?
- Why can an SVD component not be read as a topic?
- Why is NMF's error always a little above the SVD's?
In the lab: step 3 and the simulation more topics for NMF (overview page). Next: the fundamental slides of E3.3 BERTopic.