20. Stable Diffusion
Chapters 16 to 19 assembled the parts. This chapter is where they become a system you can run.
Stable Diffusion4 is not one idea; it is four, stacked, and the stack is what made image generation go from a research demo requiring a cluster to something that runs on a laptop:
- A diffusion process that turns generation into a long sequence of easy denoising problems.
- A latent space, from a VAE, so that sequence runs in a space 48× smaller than pixels.
- A text encoder, from CLIP, so the process can be told what to make.
- Classifier-free guidance, so it actually listens.
The first three appear in most explanations. The fourth is usually skipped, and it is the one that turns a model which technically conditions on text into one that obeys a prompt.
Diffusion Models
Diffusion models are trained to predict a way to slightly denoise a sample in each step; after enough iterations, a result appears. The same machinery has been applied to images, speech, 3D shapes, molecules and graphs.
-
Forward diffusion
Maps data to noise by gradually perturbing it — a fixed stochastic process, no learning involved, that turns a data sample into progressively noisier ones with a Gaussian kernel.
This process is used only during training, never at inference.
-
Reverse diffusion
Undoes it, one small step at a time. This is the part that is learned, and it is what turns random noise into data at inference.
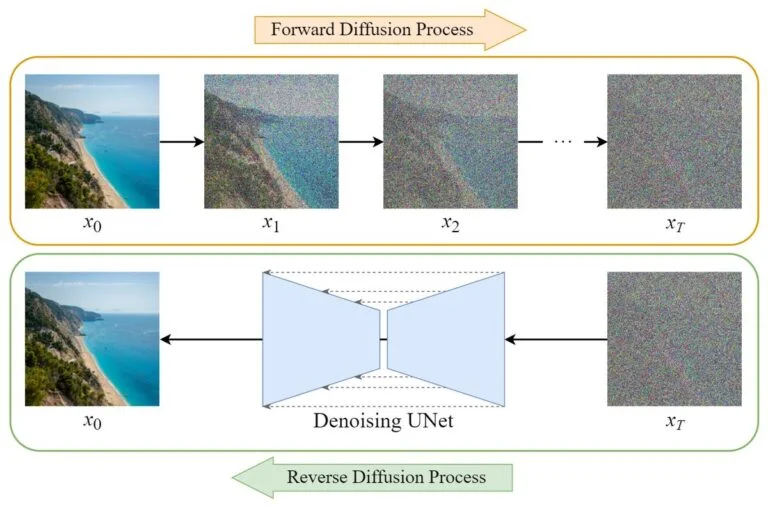
Overview of DDPM. Source: 12.
Forward diffusion
A sample \(x_0\) is corrupted with Gaussian noise over steps \(t = 1 \ldots T\):
where \(\beta_t\) is the noise schedule. Written this way it looks like a loop, and it would be useless if it were one. The step that makes diffusion trainable is that the composition of all those Gaussians is itself Gaussian, so any noise level can be reached in closed form:
Sample a random \(t\), jump straight there, and train. No simulation of the chain, no sequential dependency between training examples.
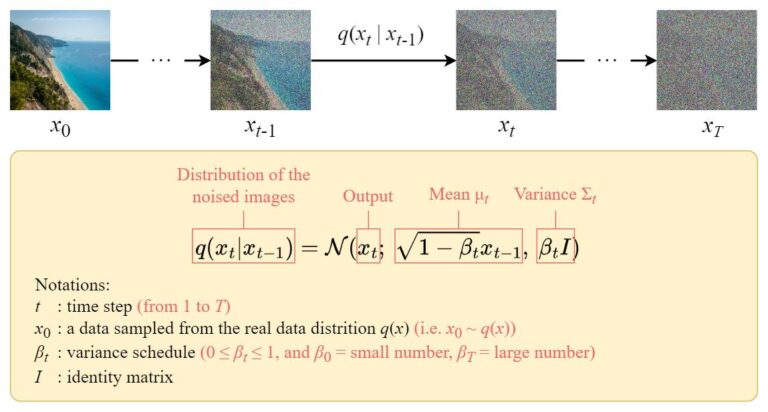
Forward diffusion. Source: 12.
The training objective is one line
Given that, what should the network predict? The elegant answer, and the one DDPM2 settled on: predict the noise that was added.
That is it. A mean-squared error between two vectors, where the target is a sample of Gaussian noise you drew yourself. It is ordinary supervised regression, which is precisely what a GAN (chapter 18) does not have, and the single largest reason diffusion displaced it: the loss goes down, and when it goes down the model is better.
Predicting noise, predicting the image, and predicting velocity
\(\epsilon\)-prediction, \(x_0\)-prediction and \(\mathbf{v}\)-prediction are algebraically interchangeable — given \(x_t\) and the schedule, any one gives the others. They differ only in how the loss is weighted across noise levels, and that weighting matters: \(\epsilon\)-prediction degrades near \(t = T\), where there is almost no signal left to divide by, which is why \(\mathbf{v}\)-prediction is standard at high resolution. See also chapter 21, where the same object reappears as a velocity field.
Reverse diffusion
Sampling runs the process backwards:
We cannot use the true \(q(x_{t-1} \mid x_t)\) — it depends on the data distribution and is intractable. The network approximates it, and the U-Net13 is the usual architecture because denoising needs both fine detail and global structure, which is exactly what an encoder–decoder with skip connections provides.
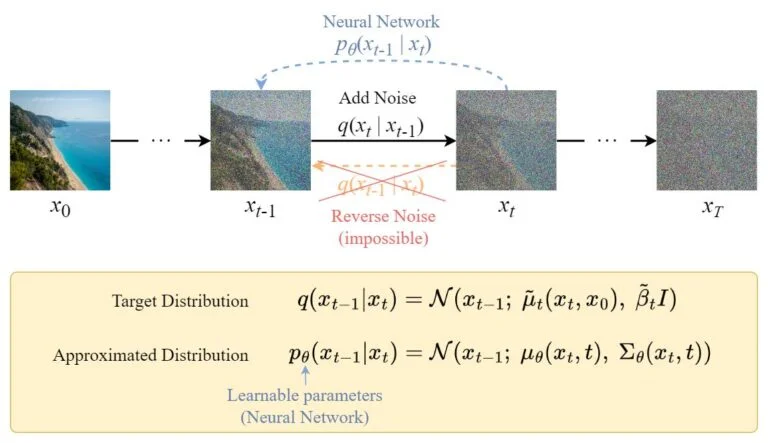
Reverse diffusion. Source: 12.
Training the U-Net
Per step: pick a random \(t\) for each image, jump to that noise level with the closed form above, embed \(t\), and regress the noise.
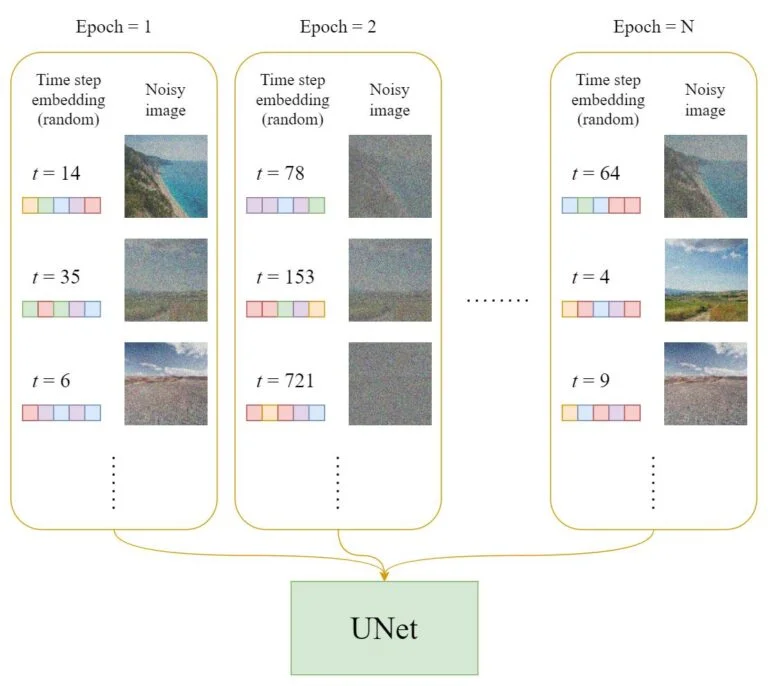
Preparing a training batch. Source: 8.
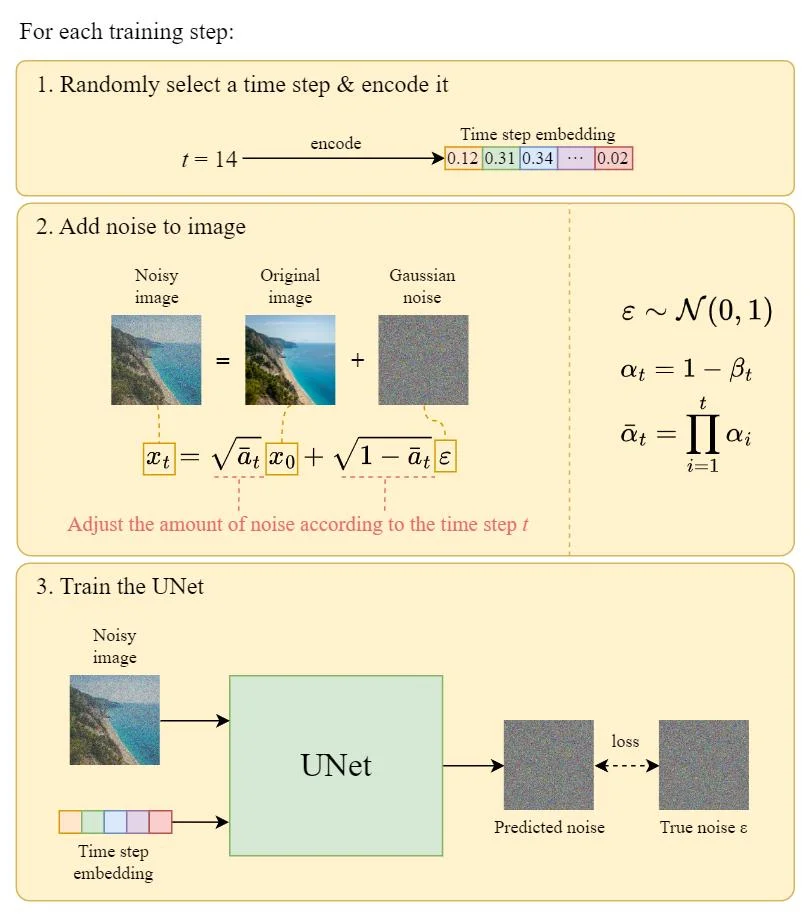
One training step. Source: 8.
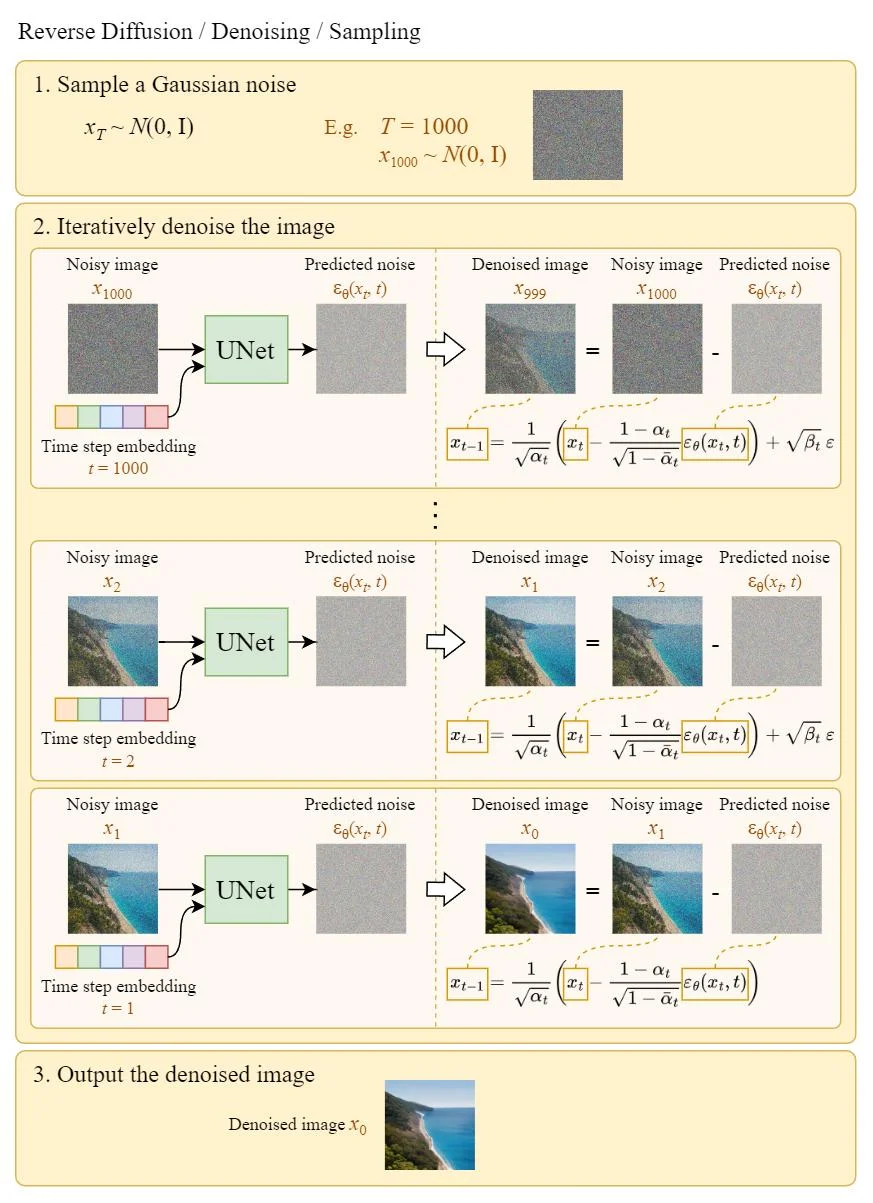
Sampling, once the network is trained. Source: 8.
The noise schedule is not a detail
\(\beta_t\) decides how much signal survives at each \(t\), and therefore what the model spends its training budget learning. Two well-known bugs live in this one function.
Terminal SNR. Stable Diffusion 1.x ships a scaled-linear schedule whose \(\bar\alpha_T \approx 0.0047\) — not zero. Training therefore always leaves a faint trace of the real image in the last step, while sampling starts from actual noise. The mismatch has a famous consequence: SD 1.x cannot produce a genuinely black or genuinely white image, because the mean brightness of the training set leaks into the first step23. Rescaling the schedule to zero terminal SNR fixes it.
Resolution. A noise level does not mean the same thing at 512 px and at 1024 px: more pixels means more redundancy, so the same \(\bar\alpha\) destroys proportionally less information. Reusing a 512-px schedule at higher resolution under-noises the image, the model is never asked to solve the structure-forming part of the problem, and the output looks like a tiled repetition of a smaller picture. SD3 makes the correction explicit as a resolution-dependent timestep shift24.
Latent diffusion: the idea that made it affordable
Running diffusion on \(512 \times 512 \times 3 = 786{,}432\) numbers, fifty times per image, is not something you do on one GPU. Latent diffusion4 moves the entire process into the VAE's latent space from chapter 17:
| Pixels | SD 1.5 latent | |
|---|---|---|
| Shape | \(512\times512\times3\) | \(64\times64\times4\) |
| Numbers | 786,432 | 16,384 |
| — | 48× less, per step, for all 50 steps |
The split is the point: the autoencoder handles perceptual detail — texture, sharpness, high frequencies — and the diffusion model handles semantics and composition. Each does the part it is good at, and the expensive part runs in the small space.
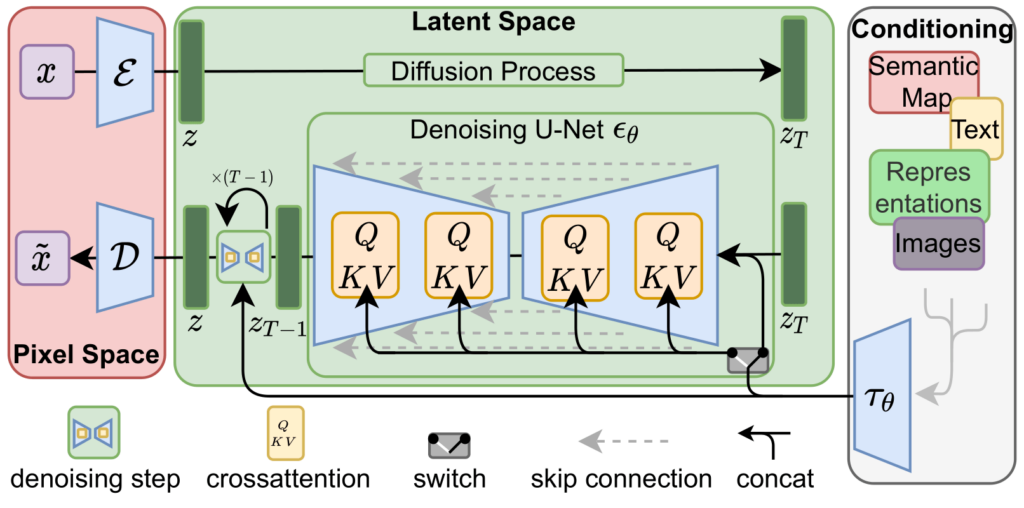
Latent diffusion. Source: 6. For a step-by-step walk through the same pipeline with every intermediate visible, the Polo Club Diffusion Explainer15 is the best companion to this section.
The three components:
- Text encoder — CLIP (chapter 19) turns the prompt into a sequence of embeddings. Frozen.
- U-Net — denoises the latent, with cross-attention layers where the query comes from the latent and key/value from the text embeddings (chapter 11). This is the only place the prompt enters, and it is exactly the cross-attention of a Transformer decoder.
- VAE — encodes to latents during training, decodes to pixels at the end of sampling. Frozen.
Milestones
graph TD
    A[2015: Diffusion Concept] --> B[2020: Denoising Diffusion Probabilistic Models - DDPM]
    B --> C[2021: Denoising Diffusion Implicit Models - DDIM]
    C --> D[2021: Latent Diffusion - LDM]
    D --> E[2022: Stable Diffusion v1<br>LDM + CLIP]
    E --> F[2022: SD 2.0]
    F --> G[2023: SDXL]
    G --> H[2024: SD3 / SD3.5]
    E --> I[<a href="https://github.com/lllyasviel/ControlNet" target="_blank">ControlNet</a>, <a href="https://arxiv.org/abs/2308.06721" target="_blank">IP-Adapter</a>, <a href="https://arxiv.org/abs/2106.09685" target="_blank">LoRA</a>]
    E --> J[Text-to-3D: DreamFusion → Magic3D → ...]
    H --> K[2024: FLUX.1 — rectified flow + MMDiT]
    K --> L[2024-26: few-step distillation<br>LCM · Turbo · Lightning]
    H --> M[2024-26: video<br>SVD → Sora-class latent video diffusion]
    click A "https://arxiv.org/abs/1503.03585" "Deep Unsupervised Learning using Nonequilibrium Thermodynamics"
    click B "https://arxiv.org/abs/2006.11239" "Denoising Diffusion Probabilistic Models"
    click C "https://arxiv.org/abs/2010.02502" "Denoising Diffusion Implicit Models"
    click D "https://github.com/CompVis/latent-diffusion" "Latent Diffusion Models"
    click E "https://huggingface.co/blog/stable_diffusion" "Stable Diffusion v1 Release"
    click F "https://stability.ai/news/stable-diffusion-v2-release" "Stable Diffusion 2.0 Release"
    click G "https://arxiv.org/abs/2307.01952" "SDXL: High-Resolution Image Synthesis with Latent Diffusion Models"
    click K "https://github.com/black-forest-labs/flux" "FLUX.1 by Black Forest Labs"
The pipeline, end to end
Inference
graph TD
    A[Text Prompt] --> B(CLIP Text Encoder)
    B --> C[Text Embedding]

    D[Random Noise<br><small>Latent</small>] --> E[Diffusion Model<br><small>UNet + Scheduler</small>]
    C --> E

    E --> F[Latent Image<br><small>after denoising</small>]

    F --> G(VAE Decoder)
    G --> H[Final Image<br><small>in pixels</small>]

    subgraph "Latent Space"
        D
        E
        F
    end

    style A fill:#a8e6cf,stroke:#333
    style B fill:#ffccbc,stroke:#333
    style C fill:#ffccbc,stroke:#333
    style D fill:#ffd3b6,stroke:#333
    style E fill:#dcedc1,stroke:#333
    style F fill:#dcedc1,stroke:#333
    style G fill:#c7ceea,stroke:#333
    style H fill:#c7ceea,stroke:#333
graph TD
A["Text Prompt<br>'A cat in space'"] --> B["CLIP Text Encoder<br><small>(Transformer)</small>"]
B --> C["Text Embedding<br><small>(77 tokens × 768 dim)</small>"]
D["Random Gaussian Noise<br>z₀ ~ N(0,1)<br><small>(4 × 64 × 64)</small>"]
subgraph Diffusion_Model ["Diffusion Model<br>(Latent Space)"]
direction TB
E["UNet with Cross-Attention<br>Predicting noise ε(θ)"]
F["Scheduler<br><small>DDIM, PLMS, etc.</small>"]
G["Cross-Attention Layers<br>Query: latent image<br>Key/Value: CLIP embedding"]
D --> E
C --> G
G --> E
E --> F
F --> H{Denoising Loop<br>T steps}
H -->|Step t| E
end
H --> I["Final Latent Image<br>ẑ_T<br><small>(4 × 64 × 64)</small>"]
I --> J["VAE Decoder"]
J --> K["Final Image in Pixels<br><small>(3 × 512 × 512)</small>"]
subgraph Training ["Training<br><small>optional</small>"]
L["Real Image<br>(3 × 512 × 512)"] --> M["VAE Encoder<br>(Downsampling)"]
M --> N["Latent Image<br>z = μ + σ⊙ε"]
N --> O["Add Noise<br>q(z_t | z_0)"]
O --> E
end
classDef text fill:#fadadd,stroke:#e74c3c,stroke-width:2px
classDef latent fill:#fff2cc,stroke:#f39c12,stroke-width:2px
classDef pixel fill:#d5f5e3,stroke:#27ae60,stroke-width:2px
classDef model fill:#ebebeb,stroke:#7f8c8d,stroke-width:2px
class A,C text
class D,I latent
class K,L pixel
class B,E,F,G,J modelClassifier-free guidance: the part that makes it obey
A model trained on (image, caption) pairs conditions on text, and if you sample from it honestly the prompt adherence is disappointing. Every text-to-image system you have used therefore does something that is not sampling from its own distribution.
Train the model with the caption dropped 10% of the time, so one network learns both the conditional score \(\epsilon_\theta(x_t, c)\) and the unconditional one \(\epsilon_\theta(x_t, \varnothing)\). Then, at every sampling step, evaluate both and extrapolate past the conditional25:
At \(w = 0\) you get the unconditional model. At \(w = 1\), plain conditional sampling. Past that you are amplifying the direction the prompt points in — which is not sampling from any distribution the model learned, and works anyway.
The panel sweeps \(w\) and measures the three things that trade against each other. Prompt adherence rises fast; diversity falls monotonically from the very first step past 1; and past roughly 10, samples are pushed off the data manifold entirely — which in a real image is the over-saturated, burnt, high-contrast look everyone recognizes from a guidance scale of 20.
Guidance doubles your inference cost
Two forward passes per step, one of which you compute in order to subtract it. Half the compute of every image you have ever generated went into the unconditional branch. Distilling guidance into the model — so a single pass produces the guided prediction — is one of the standard tricks for making few-step models fast.
Samplers: the same model, five to fifty steps
Training gives you \(\epsilon_\theta\). Turning it into an image is a separate numerical problem: integrate a reverse ODE or SDE, and you may choose the solver. This is why the same checkpoint runs at 50 steps or 20 with almost no visible difference.
| Sampler | What it is | Typical steps |
|---|---|---|
| DDPM2 | The original ancestral, stochastic sampler | 1000 |
| DDIM3 | Deterministic; reinterprets the process as an ODE, so steps can be skipped. Also makes the noise→image map invertible, which is what image editing needs | 50 |
| Euler / Heun | Plain ODE solvers on the same field | 20–30 |
| DPM-Solver++26 | An exact-exponential-integrator solver exploiting the semi-linear structure. The practical default | 15–25 |
| UniPC, DEIS | Higher-order multistep variants | 10–20 |
The step count is a dial, and it is not the only one
Fewer steps is cheaper and eventually blurrier or structurally wrong. Stochastic samplers correct accumulated error and need more steps; deterministic ones are reproducible from the seed and cheaper. Below ~10 steps no solver saves you — that regime requires distillation, not a better integrator.
Distillation: from fifty steps to one
A separate line of work compresses the sampling trajectory into the weights.
| Method | Idea | Steps |
|---|---|---|
| Progressive distillation27 | Train a student to take two teacher steps at once. Repeat. | 50 → 4 |
| LCM / LCM-LoRA28 | Consistency: learn a map from any point on the trajectory straight to its endpoint. Shipped as a LoRA that converts an existing model | 2–8 |
| SDXL-Turbo / ADD29 | Add a discriminator — the GAN loss from chapter 18 — so one-step outputs look real rather than averaged | 1–4 |
| Lightning, Hyper-SD | Combinations of the above | 1–8 |
Note what the last row implies: the GAN, displaced as a generator, came back as the thing that makes diffusion real-time. And note the honest cost — few-step models trade diversity for speed, which you will see immediately if you sample the same prompt twenty times.
Control: everything you actually do with it
Text is a poor interface for "put the subject here, in this pose". Four mechanisms cover almost every real workflow:
| Mechanism | What it does | How |
|---|---|---|
| img2img | Start from an existing image instead of pure noise | Encode it, add noise to some intermediate \(t\), denoise from there. The strength is just which \(t\) you start at |
| Inpainting | Regenerate a masked region | At every step, replace the unmasked latent with the (correctly noised) original |
| ControlNet21 | Condition on structure — a pose skeleton, a depth map, an edge map | A trainable copy of the encoder half, added into the frozen U-Net through zero-initialized convolutions, so training starts as the identity |
| IP-Adapter22 | Condition on a reference image — style or identity | Extra cross-attention layers that read CLIP image embeddings |
| LoRA | A style, a character, a concept | Chapter 14, applied to the U-Net's attention layers. This is the entire community fine-tuning ecosystem |
The pattern shared by ControlNet, IP-Adapter and LoRA
All three freeze the base model and add a small trainable path initialized to do nothing. That is why they compose — you can stack a LoRA, a ControlNet and an IP-Adapter on one checkpoint — and why the community can produce thousands of adapters for a model nobody re-trains. It is the same idea as chapter 14, transplanted into a generative model.
What changed after SD 1.5
The milestone chart above stops being informative around 2023. Here is what each generation actually changed, which is more useful than the version numbers:
| SD 1.5 (2022) | SDXL (2023) | SD 3 / FLUX (2024) | |
|---|---|---|---|
| Backbone | U-Net, 860M | U-Net, 2.6B + refiner | MMDiT — a Transformer (chapter 22) |
| Text encoder | CLIP ViT-L | Two CLIP encoders | Two CLIP + T5-XXL |
| Latent | 4 channels | 4 channels | 16 channels |
| Objective | \(\epsilon\)-prediction, DDPM | \(\epsilon\)-prediction | Rectified flow (chapter 21) |
| Native size | 512² | 1024², multi-aspect | 1024²+, resolution-shifted schedule |
Four themes, and none of them is "more parameters":
- The U-Net became a Transformer. Better scaling, and one architecture shared with everything else in the course.
- Better text encoding. T5 alongside CLIP, because CLIP's text tower is small and behaves like a bag of words (chapter 19) — which is exactly why SD 1.5 could not spell or handle long compositional prompts.
- A richer latent. 4 → 16 channels: less lost in compression, which is where legible text in generated images came from.
- Diffusion became flow matching. Straighter paths, fewer steps, simpler objective. That is the next chapter.
Where the training data came from
SD 1.x was trained on LAION-5B: image-URL pairs scraped from Common Crawl, filtered by CLIP similarity (chapter 19). Nobody whose work is in it was asked. The consequences are not hypothetical — active litigation over training data, models that reproduce a named living artist's style on request, documented memorization of individual training images, and, in one audit, illegal material that forced the dataset offline. If you build on these models, you inherit all of it. Provenance is an engineering property of your system, not a footnote.
Key takeaways
- Diffusion turns generation into many easy denoising problems, and the closed form \(x_t = \sqrt{\bar\alpha_t}x_0 + \sqrt{1-\bar\alpha_t}\epsilon\) is what makes training parallel.
- The loss is an ordinary MSE against noise you drew yourself. Stable, monotone, and the main reason diffusion beat GANs.
- The noise schedule decides what the model learns. Non-zero terminal SNR is why SD 1.x cannot render black; resolution changes what a noise level means, hence timestep shifting.
- Latent diffusion runs the process in a 48×-smaller space. The VAE handles detail, the diffusion model handles semantics.
- Classifier-free guidance is one line, doubles inference cost, and is what makes the model obey the prompt. It trades diversity for adherence, and too much of it pushes samples off-manifold.
- The sampler is a separate choice from the model. DPM-Solver++ at 15–25 steps is the practical default; below ~10 steps you need distillation, not a better solver.
- Distillation reaches 1–4 steps, and the winning method uses an adversarial loss — the GAN, returning as a component.
- ControlNet, IP-Adapter and LoRA all freeze the base and add a zero-initialized path. That is why they compose.
- Since SD 1.5: Transformer backbone, better text encoders, 16-channel latents, rectified flow. Not "bigger".
Additional
DDPM vs DDIM
| Aspect | DDPM | DDIM |
|---|---|---|
| Background | Probabilistic | Deterministic |
| Speed | More steps (slower) | Fewer steps (faster) |
| Quality | High variability | More consistent |
SDE

Denoising Diffusion Probabilistic Models (DDPM) and Score-based Generative Modeling through Stochastic Differential Equations (SDE). Source: 7.
U-Net Architecture
U-Net is a convolutional neural network architecture originally designed for biomedical image segmentation13. It has since been widely adopted in various image generation tasks, including diffusion models like Stable Diffusion. The U-Net architecture is characterized by its U-shaped structure, which consists of an encoder (contracting path) and a decoder (expanding path) with skip connections between corresponding layers.
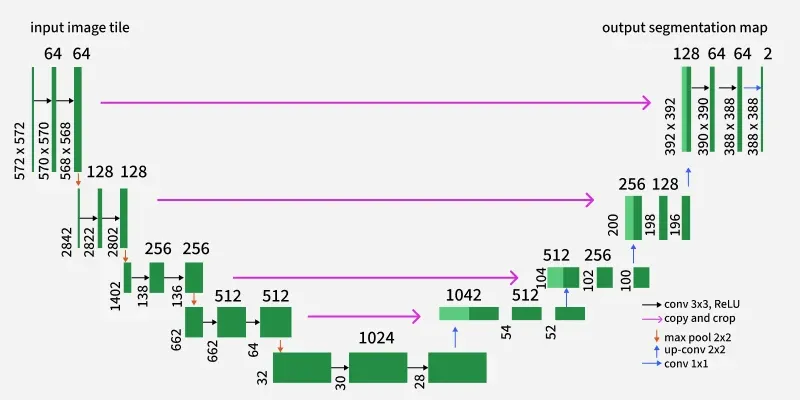
U-Net Architecture. Source: 14.
Stable Diffusion U-Net Architecture
graph TD
    subgraph Input
        Z["Noisy Latent z_t<br>(B,4,64,64)"]
        T[Timestep t]
        C["CLIP Text Emb<br>(B,77,768)"]
    end

    Z --> ConvIn[Initial Conv<br>→ 320 ch]
    T --> TEmb[Sinusoidal → MLP → 320]
    C --> CProj[Linear 768→320]

    ConvIn --> D1[Down Block 1<br>320 → 320]
    D1 --> P1[Downsample]
    P1 --> D2[Down Block 2<br>320 → 640]
    D2 --> P2[Downsample]
    P2 --> D3[Down Block 3<br>640 → 1280]
    D3 --> P3[Downsample]
    P3 --> Bottleneck[Bottleneck<br>1280 ch + Self-Attn]

    %% Skip connections
    D1 --> S1[Skip 1<br>320,32x32]
    D2 --> S2[Skip 2<br>640,16x16]
    D3 --> S3[Skip 3<br>1280,8x8]

    Bottleneck --> U1[Up Block 1<br>+ Skip 3]
    S3 --> U1
    U1 --> Up1[Upsample]
    Up1 --> U2[Up Block 2<br>+ Skip 2 + Cross-Attn]
    S2 --> U2
    CProj --> U2
    U2 --> Up2[Upsample]
    Up2 --> U3[Up Block 3<br>+ Skip 1 + Cross-Attn]
    S1 --> U3
    CProj --> U3

    U3 --> Out[Final Conv<br>→ 4 ch]
    Out --> Eps["ε_pred(z_t, t, c)"]

    style Z fill:#ffd3b6
    style Eps fill:#a8e6cf
    style Bottleneck fill:#ff9999
    style U1,U2,U3 fill:#dcedc1
Videos
Deepia: Diffusion Models: DDPM | Generative AI Animated
Deepia: Score-based Diffusion Models | Generative AI Animated
But how do AI images and videos actually work? | Guest video by Welch Labs
-
Deep Unsupervised Learning using Nonequilibrium Thermodynamics, 2015. ↩
-
Latent Diffusion Models, 2021. ↩↩
-
Dagshub - Stable Diffusion: Best Open Source Version of DALL-E 2 ↩
-
Score-Based Generative Modeling through Stochastic Differential Equations ↩
-
U-Net: Convolutional Networks for Biomedical Image Segmentation ↩↩
-
GeeksForGeeks - U-Net Architecture Explained ↩
-
Stable Diffusion Models, by Ankit Kumar. ↩
-
Flow-Matching: A New Paradigm for Generative Modeling, 2022. ↩
-
Zhang, L., Rao, A., & Agrawala, M. (2023). Adding Conditional Control to Text-to-Image Diffusion Models — ICCV. ControlNet, and the zero-initialized convolution that makes it safe to add. ↩
-
Ye, H., et al. (2023). IP-Adapter: Text Compatible Image Prompt Adapter for Text-to-Image Diffusion Models. ↩
-
Lin, S., Liu, B., Li, J., & Yang, X. (2024). Common Diffusion Noise Schedules and Sample Steps are Flawed — WACV. Where the non-zero terminal SNR bug is diagnosed and fixed. ↩
-
Esser, P., et al. (2024). Scaling Rectified Flow Transformers for High-Resolution Image Synthesis — ICML. SD3: MMDiT, rectified flow, and the resolution-dependent timestep shift. ↩
-
Ho, J., & Salimans, T. (2022). Classifier-Free Diffusion Guidance — NeurIPS workshop. Two lines of method, and one of the highest-impact papers in the field. ↩
-
Lu, C., et al. (2022). DPM-Solver++: Fast Solver for Guided Sampling of Diffusion Probabilistic Models. ↩
-
Salimans, T., & Ho, J. (2022). Progressive Distillation for Fast Sampling of Diffusion Models — ICLR. ↩
-
Luo, S., et al. (2023). Latent Consistency Models: Synthesizing High-Resolution Images with Few-Step Inference. ↩
-
Sauer, A., Lorenz, D., Blattmann, A., & Rombach, R. (2023). Adversarial Diffusion Distillation. SDXL-Turbo. ↩
-
StreamDiffusion, suggested by Pedro Fracassi. ↩